# Ayobami Adewole — Full Blog Content
> Complete content of every post on ayobamiadewole.com, converted to Markdown. See /llms.txt for a shorter curated index.
Generated at build time from 55 posts.
---
## What I've Been Building: Alehra
URL: https://www.ayobamiadewole.com/Blog/what-ive-been-building-alehra/
Category: Projects
Published: 2025-12-23
Summary: Alehra is a practice operating system for behavioral health providers, therapists, counselors and psychologists, built by the author alongside their day job. It began as a white-labeled deployment and now serves more than 250 providers and 3,000 patients.
If you've followed this blog for a while, you've mostly seen posts about testing methodologies, CI/CD pipelines, and the occasional dive into machine learning in .NET. This post is a bit different. I want to introduce something I've been building for the past couple of years alongside my day job: Alehra, a practice operating system for health providers, therapists, counselors, and psychologists.
## Why not just use an existing EHR?
Most EHR software on the market was built for general medical practices and later adapted for behavioral health. That adaptation shows up in small but constant friction: note templates that don't match how therapy sessions actually unfold, billing workflows built around procedure codes rather than session-based care, and telehealth bolted on as an afterthought rather than built in from the start.
Alehra is built specifically for behavioral health from the ground up, and that shows up in a few concrete ways. Documentation is ambient rather than manual: the system listens during a session and drafts a clinical note using templates a practice can customize to match their own language and structure, instead of forcing clinicians into a rigid form. An AI agent reviews each note for clinical concerns and helps track progress against a client's treatment plan over time, something general-purpose EHRs typically don't attempt at all. Telehealth runs natively rather than through a bolted-on third-party link, and the same ambient documentation works whether a session happens in person or on screen. Billing is unified across payment providers, with funds going directly to the practitioner rather than sitting with an intermediary.
The result is a single system instead of the four or five disconnected tools a lot of practices are stitching together today.
## The engineering behind it
For readers who come here for the technical content, here's a bit of what's under the hood. The frontend is React, and the backend is a mix of microservices in Node.js/TypeScript and Python with FastAPI. The ambient documentation feature runs on a mix of large language models. Everything runs on GCP. Cursor with assistance through Claude Code & Codex have been my primary tools for a lot of the day-to-day implementation work, which is its own interesting story about how AI-assisted coding changes what a two-person technical team can ship.
## Where things stand
Alehra started as a white-labeled deployment that grew to serve more than 250 providers and 3,000 patients. We're working through APA certification in the US and Alberta, building partnerships with the Canadian Psychological Association and the Psychologists' Association of Alberta, and starting to plan an expansion into behavioral health markets across Africa.
I'll probably write more here about the technical decisions behind Alehra as we go, from real-time telehealth to how we've approached hallucination hardening in the clinical documentation pipeline. For now, if you want to see what we've built, you can find it at [alehra.com](https://alehra.com).
### Frequently asked questions
**What is Alehra?**
A practice operating system for health providers, therapists, counselors and psychologists that the author has been building for the past couple of years alongside a day job. You can find it at alehra.com.
**How is Alehra different from a general-purpose EHR?**
It is built for behavioral health from the ground up. Documentation is ambient: the system listens during a session and drafts a clinical note from templates a practice can customize. An AI agent reviews each note for clinical concerns and tracks progress against the treatment plan. Telehealth is native, and billing is unified across payment providers with funds going directly to the practitioner.
**What technology is Alehra built with?**
A React frontend and a backend of Node.js/TypeScript and Python (FastAPI) microservices, with ambient documentation running on a mix of large language models. Everything runs on GCP.
**How big is Alehra and what is next for it?**
It started as a white-labeled deployment and grew to serve more than 250 providers and 3,000 patients. The team is working through APA certification in the US and Alberta, building partnerships with the Canadian Psychological Association and the Psychologists' Association of Alberta, and planning expansion into behavioral health markets across Africa.
---
## Swarm Testing
URL: https://www.ayobamiadewole.com/Blog/Swarm-Testing/
Category: Management
Published: 2022-07-11
Summary: Swarm testing applies swarming (mobbing) to software testing: a team meets for a 30 to 45 minute huddle to test a feature before release, using prepared test plans and Jira tickets for bugs. It complements existing QA rather than replacing it.
#### Introduction
Swarming also known as mobbing or huddling is now increasingly being used in software engineering. This is a process where a team or group of people agree to collectively tackle a task, resolve an issue or incident. This approach was traditionally used when a team must complete a task given a limited time. It is known to facilitate knowledge sharing and collaboration within a team.
When swarming process is applied to software testing, this is referred to as Swarm Testing. During swarm testing, a team organizes a huddle to test a feature of a software product before the eventual release. This process is not to replace but complete the existing quality assurance processes for software engineering cycle that a team might already have in place. This type of testing is effective at reducing cycle time, improving coverage and fault detection.
#### Swarm Testing Session
The engineer or the lead of a project is expected to consult with the team to determine if the features of the project to be tested qualifies for a swarm testing session. The project lead will identify the participants of the session and send out the meeting invites. The recommended approach is to have a mix of members that worked on the product features and those that did not.
Test plans and scenarios are to be prepared ahead and allocated to the participants. The appropriate duration of the session should be determined based on the number of test plans to be covered. It is recommended to keep the session between 30 to 45 minutes for optimal focus and participation.
Before each swarm testing session, the project lead will create the test plans and scenarios in a document or repository that is accessible to all the participants. The test plans should not contain tests already covered in the unit or end to end tests for the feature. A document or wiki page should be created using the template available later in this post. The swarm testing session document or wiki page should be filled by the project lead and shared with session attendees before the session.
During the session, the project lead will introduce the new feature by presenting the end to end flow of the most common use cases. The role of each participant in the session is to have their environment and test accounts set up if necessary. For example, some test plans require certain access or privileges, these priviledges should be requested before the session.
Any participant can create the Jira ticket for any issue or bug detected during the session. The jira ticket created should include a detailed description of what the issue is, steps to reproduce and the screenshot of the issue if applicable.
#### Swarm Testing Template
This template is a guideline that could be used in preparation for a swarm testing session. The template provides details about the session and guideline for participants on what to focus on during the session and where to log the outcome of the tests.
**Project Details**
**Project:**
< Link to project page >
**Feature Flag:**
< Feature Flag >
**Date & Time:**
< Date & Time >
**Product & Technical Documents**
< Link to Docs >
**Design Assets:**
< Link to Figma >
**Jira Epic**
< Link to Jira Epic >
**Attendees**
**Project Lead(s):**
< Link to Profile >
**Team members that worked on the feature:**
< Link to Profile >
**Other team members:**
< Link to Profile >
**EM, Design & PM:**
< Link to Profile >
**Environment Setup**
These are the requirements to be met by each participant for the session.
##### Tools & Access:
* dev/staging/prod access
* Access to Jira backlog
##### Test Accounts:
* Brand-new account, no data
* Account with some test data
* Account with lots of test data
##### Browsers:
* Google Chrome
* Safari
* Firefox
* iOS/Android browser
**Test Plans**
**For PM, Design & EM**
Focus on design patterns and user flow
< Link to test plan >
< Link to test plan >
**Other team members:**
< Link to test plan >
< Link to test plan >
**Team members that worked on the feature:**
< Link to test plan >
< Link to test plan >
**Filing bug or issues**
Participants will update this section with links to jira bug tickets, for PM to prioritize.
**Jira Bug Ticket Link**
**Check if Blocking Release**
< Link to Jira ticket created >
< Link to Jira ticket created >
table, th, td { border: 1px solid black; border-collapse: collapse; padding: 5px; margin: 5px; }
### Frequently asked questions
**What is swarm testing?**
When a team organizes a huddle to collectively test a feature of a software product before release, applying swarming (also called mobbing or huddling) to testing. It is meant to complete, not replace, the QA processes a team already has.
**How long should a session be and who should attend?**
The recommended length is 30 to 45 minutes for optimal focus and participation. Invite a mix of team members who worked on the feature and those who did not, plus engineering management, design and product.
**How are test plans and bugs handled?**
The project lead prepares test plans and scenarios in advance in a shared document or repository, excluding tests already covered by unit or end-to-end tests. Any participant can create a Jira ticket for a problem, with a description, steps to reproduce and a screenshot if applicable.
---
## Agile Story Estimation
URL: https://www.ayobamiadewole.com/Blog/Story-Estimation/
Category: Management
Published: 2022-05-28
Summary: Story points measure a story's relative effort and complexity, commonly on a Fibonacci scale (1, 2, 3, 5, 8, 13...). Teams size stories in backlog refinement with planning poker, discuss differing estimates, agree on a number, and split stories above the agreed limit.
**Introduction**
Agile story estimations can be done through the use of time or story points. The story points approach is popular and widely used by team because the story points are assigned to a story in the backlog as a measure of relative effort and complexity of that story. This blog post intent is not to teach the team to achieve perfect or accurate estimation, but to assist the team in achieving reliable velocity. With reliable velocity, the team can easily predict how long it would take to deliver a unit of work in the backlog. A unit of work could be a milestone or an epic.
**Velocity**
A team’s velocity is a measurement of the number of estimation units that the team completes sprint after sprint. The velocity is based on the number of stories that have successfully been completed in the past. This means when starting a new sprint, the team is able to use the velocity metrics as an indication to determine the number of stories in the backlog that can be realistically completed in the sprint. Additionally, when the team has reliable velocity, the team can confidently predict how long it will take to deliver a milestone, while putting other factors into consideration ( PTO, On-point/On-Call e.t.c).
**Story point size**
The size of stories is estimated using the Fibonacci Agile Estimation approach, which uses the Fibonacci sequence as a scale for estimating story points. The Fibonacci sequence is as follows: 1, 2, 3, 5, 8, 13, 21, 34, 55, 89… and so on, where each number is the sum of the preceding numbers. In essence, a task estimated as 2 story points is expected to be twice as complex and requires double efforts to complete as a task estimated as 1 story point. Also, 3 story points should equal triple the effort and complexity compared to 1 story point.
A team can adopt a story point sizing approach where 1 is the minimum point and 5 is the maximum point that can be assigned to any story. If there is a story bigger than the agreed limit (8, 13, or more) then it should be split into smaller stories or tasks. Smaller stories facilitate precise estimation.
For example, a story to change the copy of a button in a react component might be assigned a 1 story point. While a story to update routing for the some backend endpoints might be assigned a 5 story point, because of the effort and the complexity required to complete the story.
**Assigning story point**
Ideally a team will size the stories in the backlog during the backlog grooming or refinement session. During this session, the backlog items are reviewed, discussed, sized and prioritized. When attempting to estimate a story, the team will discuss some questions related to the story, such as:
1. How much work is involved?
2. How complex is the work?
3. Will the team be able to complete the story given the current technical abilities?
4. What are the potential risks?
5. Are there requirements that need further clarification or investigation?
6. Will the team require collaboration or help from other teams?
7. Have we considered everything in the definition of done?
A planning poker agile estimation technique can be used to size each story. Each team member will provide a Fibonacci number ( 1, 2, 3, 5, e.tc.) that depicts the size of the story being reviewed, based on the complexity and required effort to implement. The process will not involve the use of actual cards, but team members can send in the story points to the message channel used for the grooming session, in a coordinated voting manner.
**How is it done?**
For example, let's assume in a backlog grooming session, the team is trying to size a story – ‘Migrate logs to Splunk’. The team will have to discuss the story based on the questions discussed above. After the efforts, complexity and uncertainty have been determined, the team can proceed to attempt estimation, using the planning poker approach. If there are three members in the grooming session, the team can have the same story estimated differently as below:
1. Estimation by first member = 1
2. Estimation by second member = 2
3. Estimation by third member = 5
The estimation from the first and second team members are close, but the third team member gave the story a 5 point. The third team member would explain why they think the story is bigger. The team will discuss, review and eventually agree on the appropriate point to assign to the story before moving on to estimate the next story in the backlog. This process is repeated until all the stories in the backlog has been groomed.
### Frequently asked questions
**What is a story point?**
A measure of the relative effort and complexity of a story in the backlog, used as an alternative to estimating in units of time.
**Why is the Fibonacci sequence used for estimation?**
The Fibonacci Agile Estimation approach uses the Fibonacci sequence (1, 2, 3, 5, 8, 13, 21, 34, 55, 89...) as the scale for story points.
**What should a team do with a story that is too big?**
If a story exceeds the agreed limit (such as 8 or 13), it should be split into smaller stories or tasks, since smaller stories allow more precise estimation.
**What is velocity?**
The number of estimation units a team completes sprint after sprint, based on the stories it has completed in the past. Teams use it to plan how much to take on in a new sprint.
---
## Django deployment to Google App Engine with Github Action
URL: https://www.ayobamiadewole.com/Blog/Github-Actions/
Category: Python
Published: 2021-02-01
Summary: A GitHub Action can deploy a Django app to Google App Engine on every push to main. The repo needs main.py, requirements.txt and app.yaml at its root, plus a workflow in .github/workflows that checks out the code and deploys it.
**Introduction**
Github action was released by Github as a feature to enable automation and customization of the development to deployment workflows for software development teams. Github actions ease the flow of execution, testing and possibly deployment of repository residing on Github. Also, Github actions provide the flexibility of creating custom flows and steps that are available in standards Continuous Integration (CI) and Continuous Deployment (CD) solutions.
Additionally, using Github actions,process or flow of reviewing codes, triaging issues and managing repository branches and updating dependent libraries in projects become very easy and seamless. The full release note and information is available here [https://github.com/features/action](https://github.com/features/action)
**Deploying Django To Google App Engine.**
Let's explore how Github actions can be used to automate deployment of a Django application hosted on Github to Google App Engine. There are different approaches to setting up Github actions for your repository and a repository can have multiple actions setup and hooked to different events. A Github action could be set up to listen to pull request merge events to a main branch, and then proceed to build, test and deploy to any of the cloud providers of choice.
In order to ensure a Django app can be deployed from Github to Google app engine, there are certain considerations and setup procedures. The root folder of your Django application should contain the following files main.py, requirements.txt and app.yaml
See a sample App.yaml file below
# App.yaml file
# https://cloud.google.com/appengine/docs/standard/python3/config/appref
runtime: python39
instance\_class: F2
env\_variables:
DJANGO\_SETTINGS\_MODULE: "settings"
DB\_NAME: "db\_name"
DB\_USERNAME: "db\_user"
DB\_PASSWORD: "db\_password"
DB\_HOST: "/cloudsql/double-media-xxxx:europe-west1:db\_name"
DB\_PORT: 3306
DB\_TIMEOUT: 5000
handlers:
# This configures Google App Engine to serve the files in the app's static
# directory.
- url: /static
static\_dir: static/
# This handler routes all requests not caught above to your main app. It is
# required when static routes are defined, but can be omitted (along with
# the entire handlers section) when there are no static files defined.
- url: /.\*
secure: always
redirect\_http\_response\_code: 301
script: auto
Then proceed to create .github/workflows folder in your repository root folder and create a github action to subscribe to the push event on the main branch, see the sample action file below.
# .github/workflows/deploy
# https://cloud.google.com/python/django/appengine
# https://github.com/actions-hub/gcloud:
name: deploy-app-to-gcp
on:
push:
branches: \[ main\]
paths:
- 'app/\*\*'
jobs:
deploy:
name: Deploy
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v1
- uses: actions-hub/gcloud@master
env:
PROJECT\_ID: ${{secrets.GCLOUD\_PROJECT\_PROD\_ID}}
APPLICATION\_CREDENTIALS: ${{secrets.GCLOUD\_GITHUB\_CREDENTIALS}}
with:
args: app deploy ./app.yaml
The github action posted above has depends on two other actions, the first to checkout the latest code and then deploy the Django app to Google app engine, using the credentials and project id that can be set in Github secrets.
### Frequently asked questions
**What files does a Django app need to deploy to Google App Engine?**
The root folder of the Django application should contain main.py, requirements.txt and app.yaml.
**How do I trigger the deployment from GitHub?**
Create a .github/workflows folder in the repository root and add a workflow that subscribes to the push event on the main branch. It uses two other actions: one to check out the latest code and one to deploy the app to App Engine.
**Where do the Google Cloud credentials go?**
The credentials and project id are stored as GitHub secrets, which the deploy action uses.
---
## Named entity extraction from text in Python
URL: https://www.ayobamiadewole.com/Blog/named-entity-extraction-from-text-in-python/
Category: Python
Published: 2020-01-12
Summary: Named entity recognition finds and classifies entities such as people, places, organizations, dates and money in text. The post demonstrates it with spaCy, whose models were trained on the OntoNotes 5 corpus, and compares spaCy with NLTK.
**Introduction**
The ability to understand and process natural language is regarded as one of the superiority of humans to computer. Humans if able to read and or possibly write, can readily comprehend written texts and make meanings out of the syllables, grammar, vocabulary and punctuation. Although, as simple and effortless as it might seem for humans, making meaning out of a simple text for computers requires a bit of rules, logic driven approach or machine training and adaptation.
Natural Language Processing (NLP) in Python has become commonplace, thanks to the availability of mature, open source and industrial grade readily available libraries with little learning curve. Out of the open source NLP libraries available for Python, Natural Language Toolkit (NLTK) and spaCy stand out with huge community engagement and resources.
**NLTK vs spaCy**
NLTK is a suite of open source Natural Language Processing library containing Python modules with extensive data sets and examples, with great support for research and development. Also, NLTK provides easy-to-use interfaces to numerous corpora and lexical resources such as WordNet. It includes a suite of text processing libraries for performing classification, tokenization, stemming, tagging, parsing, and semantic reasoning, wrappers on natural languages. The github code is at [https://github.com/nltk/nltk](https://github.com/nltk/nltk).
spaCy on the other is more suited for large scale Natural Language Processing tasks and is commonly used in industry and enterprise applications with NLP requirements, with support for over 50 languages. Spacy can be used together with any of Python’s AI libraries, it works seamlessly with TensorFlow, PyTorch, scikit-learn and Gensim. It is fairly easier to build linguistically advanced statistical models for a variety of NLP problems using spaCy compared to NLTK. More info on spacCy can be found at [https://spacy.io/](https://spacy.io/).
**Named Entity Recognition**
Named entity recognition (NER) is a subset or subtask of information extraction. It involves identifying and classifying named entities in text into sets of pre-defined categories. These categories include names of persons, locations, expressions of times, organizations, quantities, monetary values and so on. NER has real word usages in various Natural Language Processing problems.
Some sample usages might include
* Building a minimalistic search engine, you might want to identify locations, names or even products in search texts.
* Tweet mining, to determine if it contains locations or persons of interests.
**Named Entity Recognition using spaCy**
spaCy named entity recognition models were trained using OntoNotes 5 corpus and these models support the following entity types:
Type
Description
PERSON
People, including fictional.
NORP
Nationalities or religious or political groups.
FAC
Buildings, airports, highways, bridges, etc.
ORG
Companies, agencies, institutions, etc.
GPE
Countries, cities, states.
LOC
Non-GPE locations, mountain ranges, bodies of water.
PRODUCT
Objects, vehicles, foods, etc. (Not services.)
EVENT
Named hurricanes, battles, wars, sports events, etc.
WORK\_OF\_ART
Titles of books, songs, etc.
LAW
Named documents made into laws.
LANGUAGE
Any named language.
DATE
Absolute or relative dates or periods.
TIME
Times smaller than a day.
PERCENT
Percentage, including ”%“.
MONEY
Monetary values, including unit.
QUANTITY
Measurements, as of weight or distance.
ORDINAL
“first”, “second”, etc.
CARDINAL
Numerals that do not fall under another type.
Install spaCy library with pip and download the english model using the commands below from terminal.
pip install spacy
python -m spacy download en
We will be using text “John bought a Toyota camry 2019 model in Toronto in January 2020 at a cost of $38000” and pass this to spacy to recognize the entities in the text. Recognizing entities in a text using spaCy involves three steps.
**First step**: Loading the spaCy library
spacy\_nlp = spacy.load('en\_core\_web\_sm')
If you are using spaCy medium or large pre-trained model, use 'en\_core\_web\_md' or 'en\_core\_web\_lg' insead of 'en\_core\_web\_sm'.
**Second step**: Constructing a spaCy document from the text
text = "John bought a Toyota camry 2019 model in Toronto in January 2020 at a cost of $38000"
doc = spacy\_nlp(text.strip())
**Third step**: The doc object constructed contains loaded entities which can be accessed to extract the entities recognized
text = "John bought a Toyota camry 2019 model in Toronto in January 2020 at a cost of $38000"
doc = spacy\_nlp(text.strip())
The snippet below shows how the entities are extracted using the spaCy supported entity types.
# create sets to hold words
named\_entities = set()
money\_entities = set()
organization\_entities = set()
location\_entities = set()
time\_indicator\_entities = set()
for i in doc.ents:
entry = str(i.lemma\_).lower()
text = text.replace(str(i).lower(), "")
# Time indicator entities detection
if i.label\_ in \["TIM", "DATE"\]:
time\_indicator\_entities.add(entry)
# money value entities detection
elif i.label\_ in \["MONEY"\]:
money\_entities.add(entry)
# organization entities detection
elif i.label\_ in \["ORG"\]:
organization\_entities.add(entry)
# Geographical and Geographical entities detection
elif i.label\_ in \["GPE", "GEO"\]:
location\_entities.add(entry)
# extract artifacts, events and natural phenomenon from text
elif i.label\_ in \["ART", "EVE", "NAT", "PERSON"\]:
named\_entities.add(entry.title())
The recognized entities can be printed to the console.
print(f"named entities - {named\_entities}")
print(f"money entities - {money\_entities}")
print(f"location entities - {location\_entities}")
print(f"time indicator entities - {time\_indicator\_entities}")
print(f"organization entities - {organization\_entities}")
-------------------------------------------------------------
named entities - {'John'}
money entities - {'38000'}
location entities - {'toronto'}
time indicator entities - {'2019', 'january 2020'}
organization entities - {'toyota'}
In the output John was extracted as the named entity, 38000 as moeny entity, Toronto as location entity, Toyota as organization entity, lastly 2019 and Janauary 2020 as time indicator entities.
Complete source code listing is below.
import spacy
class NamedEntityExtractor:
"""
Performs named entity recognition from texts
"""
def extract(self, text: str) :
"""
Performs named entity recognition from text
:param text: Text to extract
"""
# load spacy nlp library
spacy\_nlp = spacy.load('en\_core\_web\_sm')
# parse text into spacy document
doc = spacy\_nlp(text.strip())
# create sets to hold words
named\_entities = set()
money\_entities = set()
organization\_entities = set()
location\_entities = set()
time\_indicator\_entities = set()
for i in doc.ents:
entry = str(i.lemma\_).lower()
text = text.replace(str(i).lower(), "")
# Time indicator entities detection
if i.label\_ in \["TIM", "DATE"\]:
time\_indicator\_entities.add(entry)
# money value entities detection
elif i.label\_ in \["MONEY"\]:
money\_entities.add(entry)
# organization entities detection
elif i.label\_ in \["ORG"\]:
organization\_entities.add(entry)
# Geographical and Geographical entities detection
elif i.label\_ in \["GPE", "GEO"\]:
location\_entities.add(entry)
# extract artifacts, events and natural phenomenon from text
elif i.label\_ in \["ART", "EVE", "NAT", "PERSON"\]:
named\_entities.add(entry.title())
print(f"named entities - {named\_entities}")
print(f"money entities - {money\_entities}")
print(f"location entities - {location\_entities}")
print(f"time indicator entities - {time\_indicator\_entities}")
print(f"organization entities - {organization\_entities}")
if \_\_name\_\_ == '\_\_main\_\_':
named\_entity\_extractor = NamedEntityExtractor()
text = "John bought a Toyota camry 2019 model in Toronto in January 2020 at a cost of $38000"
named\_entity\_extractor.extract(text)
Named entity extraction has numerous real world usages, with samples mentioned earlier. spaCy can easily be boostrapped to add this fucntionality to your enterprise application.
### Frequently asked questions
**What is named entity recognition?**
A subtask of information extraction that identifies named entities in text and classifies them into predefined categories such as persons, locations, times, organizations, quantities and monetary values.
**How do NLTK and spaCy differ?**
NLTK is a suite of Python modules with extensive datasets and examples, with great support for research and development. spaCy is better suited to large-scale, industry and enterprise NLP, supports over 50 languages, and works with TensorFlow, PyTorch and scikit-learn.
**How do I extract entities with spaCy?**
Three steps: load the spaCy library and a model, construct a spaCy document from the text, then read the recognized entities from the doc object. In the post's example it picked out a person, a money amount, a location, an organization and dates.
---
## Log Analytics in Azure
URL: https://www.ayobamiadewole.com/Blog/Log-Analytics-in-Azure/
Category: Others
Published: 2019-03-19
Summary: An excerpt from Ritesh Modi's Azure for Architects. Log Analytics (OMS) collects and searches telemetry from VMs and containers through installed agents, with no application code changes, and supports solutions and alert rules with email, webhook, runbook or ITSM actions.
**Introduction**
_Learn about Log Analytics in this article by Ritesh Modi, an ex-Microsoft Senior Technology Evangelist. He is a Microsoft Regional Director and the Regional Lead for Microsoft certified trainers._
Log Analytics service helps in providing information about environments using its rich log storage and analytic features. Application Insights is used for monitoring applications. However, it is equally important to monitor the environment on which an application is hosted and running. This involves the infrastructure, such as virtual machines, Docker containers, and related components.
**Provisioning** Log Analytics, also known as the **Operational Management Suite (OMS)**, must be provisioned on Azure before it can be used to monitor virtual machines and containers. Again, similar to Application Insights, Operational Insights can be provisioned through the Azure Portal, PowerShell, REST APIs, and resource group manager templates. An Operational Insights workspace is a security boundary that can be accessed by certain users. Multiple workspaces should be created to isolate users and their corresponding access to environment telemetry data.
The JSON script used to provision an Operational Insights workspace is shown here:
{
"apiVersion": "2015-11-01-preview",
"type": "Microsoft.OperationalInsights/workspaces",
"name": "\[parameters('workspaceName')\]",
"location": "\[parameters('deployLocation')\]",
"properties": {
"sku": {
"Name": "\[parameters('serviceTier')\]"
}
}
}
The name, location, and sku information is needed to provision a workspace, and their values are provided using parameters.
The workspace after provisioning is shown in the following screenshot:

Click on the OMS portal section to open the workspace portal. This portal is used to view all telemetry information captured by Operational Insights, configure Operational Insights, and provide dashboard features and functionality.
The home screen of Operational Insights is shown here:

The **Settings** section shows that four data sources are connected. These are four virtual machines connected to the OMS workspace from the test and production environments. A different strategy of having a separate workspace for each environment can be adopted, and it is left to readers to decide what's best for their applications and solutions. Operational Insights can be configured using the **Settings** tile:

**OMS agents**
You may have noticed that no assembly or code changes are made to the application to consume Operational Insights. Operational Insights depends on the installation of an agent on virtual machines. These agents keep collecting telemetry data from these hosts and send them to the Operational Insights workspace, where they are stored for a specified period of time depending upon the sku chosen. These agents can be installed manually on virtual machines. ARM virtual machine extensions install agents automatically, immediately after provisioning the virtual machines. The JSON code for provisioning of an agent on a virtual machine is shown here:
{
"apiVersion": "2015-06-15",
"type": "Microsoft.Compute/virtualMachines/extensions",
"name": "\[concat(variables('vmName'),copyIndex(1),'/omsscript')\]",
"location": "\[resourceGroup().location\]",
"dependsOn": \[
"\[concat('Microsoft.Compute/virtualMachines/',variables('vmName'),copyIndex(1))\]",
"\[resourceId('Microsoft.Compute/virtualMachines/extensions', concat(variables('vmName'),copyIndex(1)),'powershellscript')\]"
\],
"copy": {
"count": "\[parameters('countVMs')\]",
"name": "omsloop"
},
"properties": {
"publisher": "Microsoft.EnterpriseCloud.Monitoring",
"type": "MicrosoftMonitoringAgent",
"typeHandlerVersion": "1.0",
"settings": {
"workspaceId": "\[parameters('WorkspaceID')\]"
},
"protectedSettings": {
"workspaceKey": "\[listKeys(variables('accountid'),'2015-11-01-preview').primarySharedKey\]"
}
}
}
The **workspaceId** and **accountid** are available from the **Settings** tile of the OMS workspace, and the copy element is used to deploy it to multiple virtual machines. This resource is a child resource of the virtual machine resource, ensuring that this extension is executed whenever a virtual machine is provisioned or updated.
The configuration related to workspace ID and account ID is shown next. The primary key is used as an account ID for configuring the agents using ARM templates.

**Search**
The OMS workspace provides search capabilities to search for specific log entries, export all telemetry data to Excel and/or PowerBI, and search language specific to OMS.
The **Log Search** screen is shown here:

**Solutions**
Solutions in OMS are additional capabilities that can be added to the workspace, capturing additional telemetry data that is not captured by default. When these solutions are added to the workspace, appropriate management packs are sent to all the agents connected to the workspace in the context of configuring themselves for capturing solution-specific data from virtual machines and containers, and then start sending it to the OMS workspace.
The following screenshot shows the solution gallery and capacity and performance solution on the OMS workspace. Clicking on any solution and subsequently clicking on the **Add** button adds the solution to the workspace, as shown below:

Azure provides lots of OMS solutions for tracking and monitoring different aspects of environments and applications. At a minimum, a set of solutions that are generic and applicable to almost any environment should be added to the workspace:
* Capacity and performance
* Agent health
* Change tracking
* Containers
* Security and audit
* Update management
* Network performance monitoring
**Alerts**
Log Analytics allows us to generate alerts on the ingested data. It does so by running a pre-defined query composed of conditions on the incoming data. If it finds any records that fall within the ambit of the query, it generates an alert. Log Analytics provides a highly configurable environment for determining the conditions for generating alerts, time windows in which the query should return the records, time windows in which the query should be executed, and actions to be taken when the query returns results as alerts.

The first step in configuring an alert is to create a saved search. A saved search is simply a search query against Log Analytics, as shown below:

Save the query by providing a name for it. After saving the query, click on the **Alert** button from the **Log Search** menu. It provides the user an interface for defining and adding a new alert rule:

Within this single screen, all configurations related to an alert rule can be performed. You need to provide a name, description, severity, and the query to be executed as part of the rule evaluation within their respective fields.
The time window specifies the data interval in which the query should be executed. In the screenshot, whenever the rule is executed, it processes data from the last **15** minutes.
The schedule section helps you configure the frequency of rule execution. It answers the question, **how frequently should the query run?** In the previous screenshot, the rule is executed every **15** minutes. The time window should be more than the alert frequency. The alerts can be further configured based on the number of results found. It need not be that an alert is generated for every instance of data found based on the query. It can further be quantified to accumulate a certain quantity of results before raising the requests. The alerts can also be generated based on metric measurements. Additional configuration to suppress alerts can be done. You can create a time interval that should elapse before the action is executed. In this case, alerts are generated but the action is executed only after the configured interval has elapsed.
The **Actions**section allows us to configure things that should follow an alert. Generally, there should be a remedial and/or notification action. Log Analytics provides four different ways to create a new action. They can be combined in any way. An alert will execute any and all the following configured actions:
* **Email notification**: This is the simplest, and sends an email to the configured recipients:

* **Webhook:** A webhook executes an arbitrary external process using a HTTP POST mechanism. For example, a REST API can be executed, or the Service Manager/ServiceNow APIs can be invoked to create a ticket:

* **Runbooks:** This action executes Azure Automation runbooks.
* **ITSM actions:**ITSM solutions should be provisioned before using this option. It helps with connecting and sending information to ITSM systems.
If you found this article interesting, you can explore [Azure for Architects](https://www.amazon.com/Azure-Architects-Implementing-containers-serverless-ebook/dp/B07NDBN6XM?utm_source=%20wsvincent&utm_medium=referral&utm_campaign=ThirdPartyPromotions) to create advanced data and integrated solutions using Azure Event Grid, functions, and containers. [Azure for Architects](https://www.packtpub.com/virtualization-and-cloud/azure-architects-second-edition?utm_source=%20wsvincent&utm_medium=referral&utm_campaign=ThirdPartyPromotions) can help you develop a full-fledged Azure cloud solution that is Enterprise class and future-ready.
### Frequently asked questions
**Do I need to change my application code to use Log Analytics?**
No. It depends on installing an agent on the virtual machines. The agents keep collecting telemetry from the hosts and send it to the workspace, so no assembly or code changes are made to the application.
**What are OMS solutions?**
Additional capabilities added to the workspace to capture telemetry that is not captured by default. Generic ones the post recommends include capacity and performance, agent health, change tracking, containers, security and audit, update management and network performance monitoring.
**What actions can a Log Analytics alert trigger?**
Four kinds, in any combination: an email notification, a webhook (an HTTP POST that can run a REST API or create a ServiceNow ticket), an Azure Automation runbook, and an ITSM action, which requires ITSM solutions to be provisioned first.
---
## Logging to AWS Cloudwatch using Nlog
URL: https://www.ayobamiadewole.com/Blog/Logging-to-AWS-Cloudwatch-using-Nlog/
Category: Others
Published: 2019-03-01
Summary: NLog can send .NET application logs to AWS CloudWatch Logs: add the NLog and AWS.Logger.NLog NuGet packages, configure a CloudWatch target in NLog.config, and supply AWS credentials, preferably from a credentials file rather than hard-coded keys.
**Introduction**
The importance of logging in enterprise software application development, cannot be overemphasized. Logging is the process of recording events, inner workings, and operations, warnings and errors of software applications. Logging libraries and frameworks can generate log files, database entries, queues messages which can be used to debug, trace and monitor enterprise applications in real time.
Log entries generated can be used to troubleshoot, monitor, debug and resolve issues. Logging has also been referred to as the most powerful tool any software engineer can ever process - I totally agree with this.
**NLog**
Logging is a software development cross-cutting concern that has been made easier over the years in with the continuous introduction of new logging libraries and improvement of existing robust libraries available on Nuget.
One of such libraries is NLog - a logging library that provides support for the different .Net platforms and gives the flexibility to write log entries to numerous targets which include file, console, database and AWS console. Also, NLog flexibility permits on the fly changing of logging configuration. Read more on NLog capabilities at [https://nlog-project.org](https://nlog-project.org)
**AWS Console Logging**
Using Amazon Cloudwatch Logs service, log entries generated by logging frameworks in .Net can now be written, monitored and accessed through AWS console. AWS Cloudwatch Logs service supports NLog and other .Net logging frameworks.console.
In order to write logs to AWS cloudwatch, Nlog and AWS.Logger.NLog Nuget packages will be added to the .Net project. Afterwhich the NLog.config file generated when NLog library is added to a .Net project will have to be updated to use CloudWatch Logs as target. See the NLog configuration file below.
Once the configuration file is set, a wrapper class can be created around the logging library where the AWS keys are set and the logging specific configurations can be initialized. See the code snippet for NLogWrapper class below.
public class NLogWrapper
{
private readonly Logger logger;
public NLogWrapper()
{
Configure();
}
public void Configure()
{
var config = new LoggingConfiguration();
string accessKey = "put your access key here";
string secretKey = "put your secret key here";
var awsTarget = new AWSTarget()
{
LogGroup = "Log.ConfigPOC",
Region = "us-east-1",
Credentials = new Amazon.Runtime.BasicAWSCredentials(accessKey,secretKey)
};
config.AddTarget("aws", awsTarget);
config.LoggingRules.Add(new LoggingRule("\*", LogLevel.Debug, awsTarget));
LogManager.Configuration = config;
}
public void Info(object message)
{
logger.Info(message);
}
public void Error(Exception exception)
{
logger.Error(exception);
}
}
A much cleaner approach without having to hard code the credentials will be to have the AWS credentials in a file placed in a location in the project or the application server. The path to the credential file will then be added to app.config or web.config file like below. Where **AWSProfileName** will have the same value as the heading contained in the credential file and **AWSProfilesLocation** will contain the path to the credential file.
The content of the credential files will have the format below:
\[test\]
aws\_access\_key\_id = put key here
aws\_secret\_access\_key = put key here
The Nlog.config file will be updated with configuration entries like what is below.
Also, the NLogWrapper class will be updated and the hard coded AWS credentials and configurations will be removed, the class will be modified to to what is in the snippet below.
public class NLogWrapper
{
private readonly Logger logger;
public NLogWrapper()
{
logger = LogManager.GetCurrentClassLogger();
}
public void Info(object message)
{
logger.Info(message);
}
public void Error(Exception exception)
{
logger.Error(exception);
}
}
This will begin to write the log entries to AWS console. The log entries can be reviewed from the AWS dashboard and metrics can be built and around the logs.
### Frequently asked questions
**How do I send NLog logs to AWS CloudWatch?**
Add the NLog and AWS.Logger.NLog NuGet packages to the .NET project, then update the NLog.config file to use CloudWatch Logs as a target. Log entries can then be reviewed in the AWS console.
**Where should the AWS credentials go?**
The post first hard-codes the access and secret keys in a wrapper class, then recommends a cleaner approach: keep the credentials in a file in the project or on the application server, and add AWSProfileName and AWSProfilesLocation keys to app.config or web.config.
---
## Image to PDF Conversion using Google Script
URL: https://www.ayobamiadewole.com/Blog/Image-to-PDF-Conversion-using-Google-Script/
Category: Others
Published: 2019-01-28
Summary: In Google Apps Script, converting an uploaded photo to PDF through a base64 HTML blob can distort phone-camera images because it ignores orientation. Inserting the image into a temporary Google Doc and exporting that as a PDF keeps it correct.
**Introduction**
There are diverse providers of services for collecting data from customers and users through forms and survey. However, Google form provides the flexibility of scripting and extending the data collection and form submission processes when users interact with the forms, surveys or opinion polls created using Google form.
For most Google form creators, the default behaviour and functionalities provided out of the box can serve the data collection purposes. This is because Google makes it easy to access the data provided by users when they filled the form through response sheet attached to the form while additionally providing a response page for viewing the responses with pictorial and graphical representation of the responses.
File of supported format and types can be added to a created form, making it easy to accepts files from users. When a form has file upload in it, Google saves the uploaded file in the Google drive of the Google account that owns the form and provides the accessible url in the response sheet, giving the flexibility to download the file using the provided url.
While files of allowed format can be uploaded through the form’s file upload, Google doesn't provide an explicit way of converting files from one format to another, let's say from text or image to pdf during or after upload through the form.
For example let's say we have a form that allows users to upload invoice files which can be a pdf file or an image taken with their mobile devices, like in the screen below. There might be a requirement that necessitate the conversion of the images to pdf and then send to an email address for processing.
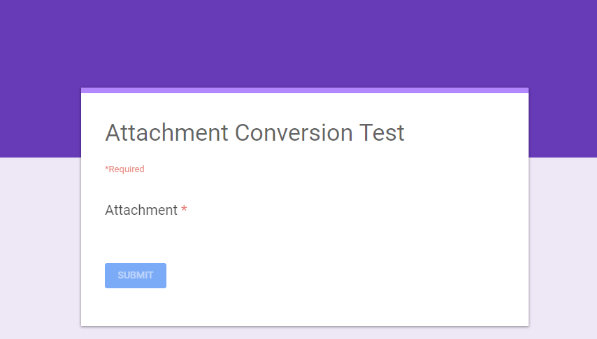
There is a well known approach which is to get the bytes of the uploaded image file, encode it into base64 and create an HTML image tag with the encoded bytes passed into the src attribute. After which Utilities class newBlob function is used to create an HTML blob from the content before finally getting a pdf blob from it, see the snippet below
function getUploadedInvoice(fileId){
var uploadedFile = DriveApp.getFileById(fileId);
var downloadUrl=uploadedFile.getDownloadUrl();
var mimeType=uploadedFile.getMimeType();
var filename=uploadedFile.getName();
var blob=null;
var fileType=mimeType.toLowerCase();
if( fileType=="image/png" || fileType =="image/jpeg"){
var base64 = Utilities.base64Encode(uploadedFile.getBlob().getBytes());
var html = '';
blob = Utilities.newBlob(html, MimeType.HTML).setName(filename + ".pdf");
blob = blob.getAs(MimeType.PDF);
}
else if(fileType == "application/pdf"){
blob = uploadedFile.getAs('application/pdf');
}
return blob;
}
This approach works and generates pdf file from the uploaded image. However, there is a limitation to it, when mobile users upload image files by directly taking the pictures using the phone camera, the above snippet doesn't handle the orientation of the image correctly, hence the final pdf has images distorted from the original look.
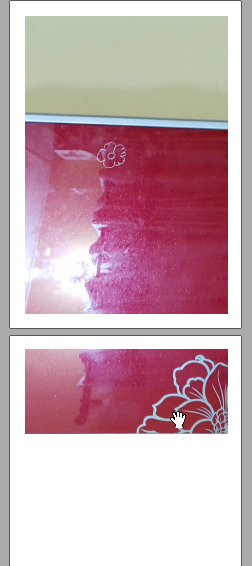
This issue can be fixed by using a different approach which is to create on the fly a temporary Google document and insert the image into the body of the document, save it and generate a pdf blob from the created file. Using this approach, the orientation of the image is always intact without being distorted. The approach uses Drive Service for creating the temporary document which the image is inserted.
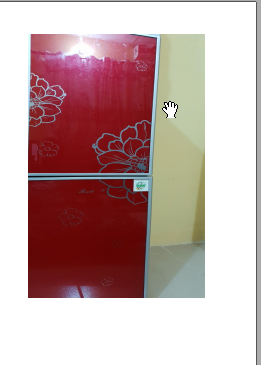
function getUploadedInvoice(fileId){
var uploadedFile = DriveApp.getFileById(fileId);
var fileType=uploadedFile.getMimeType().toLowerCase();
var blob=null;
if( fileType=="image/png" || fileType =="image/jpeg"){
var image = uploadedFile.getBlob();
var filename=uploadedFile.getName();
var doc = DocumentApp.create(filename);
var insertedImage = doc.getBody().insertImage(0, image);
resizeImage(insertedImage);
doc.saveAndClose();
blob = doc.getAs(MimeType.PDF);
tempFileId=doc.getId();
}
else if(fileType == "application/pdf"){
blob = uploadedFile.getAs(MimeType.PDF);
}
return blob;
}
function resizeImage(image) {
var height = image.getHeight();
var width = image.getWidth();
var factor = height / 800;
image.setHeight(height / factor);
factor = width / 540;
image.setWidth(width / factor);
}
### Frequently asked questions
**How do I convert an uploaded image to PDF in a Google Form with Apps Script?**
The well-known approach gets the image bytes, base64-encodes them into an HTML image tag, creates a blob with Utilities.newBlob and gets a PDF blob from it. It works, but has a limitation with phone photos.
**Why does the converted PDF look distorted?**
When mobile users take a picture directly with the phone camera, that approach does not handle the image's orientation correctly, so the PDF shows the image distorted.
**What is the fix?**
Use the Drive service to create a temporary Google Document on the fly, insert the image into its body, save it and generate the PDF blob from that document. The orientation is always kept intact.
---
## The Journey from a Blogger to an Author
URL: https://www.ayobamiadewole.com/Blog/From-a-Blogger-to-an-Author/
Category: C#
Published: 2018-11-01
Summary: How the author went from blogging to writing "C# and .NET Core Test-Driven Development": a Packt editor emailed them in 2017 after reading their 2012 TDD post, writing began in October 2017, and the book was released on 18 May 2018.
In the fall of 2015, I finally made up my mind to get a Master’s degree in Computer Science. It’s one of my numerous :) life goals that needed to be achieved at that time. After careful research and consideration, I opted for the option of combining full time work with schooling. This decision eventually turned out to be very rewarding but stressful and challenging.
Upon completing the Master’s program in September 2017, I decided to take a break from everything :) and go on vacation to celebrate the little achievement. Just few days into the vacation, I got a mail from Packt Publishing Acquisition Editor, proposing to me the idea of writing a book.
I am an Acquisition Editor at Packt. Currently I am looking for a potential author for a book titled C# and .NET Core
Test-Driven Development. This book is for .NET developers who would like to build efficient applications by
implementing principles of Test Driven development.
I read your blog on this topic and I know you are an expert. I believe your contributions as an author will be greatly
appreciated by the readers.
If writing this book interests you, please get in touch. I'd be happy to share more details.
Apparently, the editor had read an article on my blog about [Test Driven Development](http://ayobamiadewole.com/Blog/Test-Driven-Development\(TDD\)-in-Csharp) in C# that I wrote in January of 2012. It was an understatement to say I was super excited reading the mail, this is because I have always been very passionate about being an author. And to crown it, I was to write on Test Driven Development, a concept I have been enthusiastic about right from when I started enterprise software development.
Series of emails were exchanged which necessitated reviewing the book brief, working on the outline and signing the book contract after a go ahead from Legal Adviser, I eventually started writing the book in October 2017.
Setting out to write the book made me realize there is a clear difference from being a blogger and being an author. Just like blogging, when writing a book, you must choose a style of writing, be clear, concise and assertive. However, you must be ready to work with content editor, technical editor and reviewers, who will constructively edit and criticize the writeup. Fortunately for me the team of professionals and experts at Packt Publishing assisted me in the journey of transitioning from being a blogger to an author.
In mid-May, 2018, after months of writing the book’s contents, editing and reviewing by the team of professionals at Packt, I finally woke up to this golden mail from the Acquisition Editor.
Congratulations on the publication of C# and .NET Core Test-Driven Development!
We have a fantastic end product with this book as a result of everyone's hard work and especially your dedication
and patience.
It was an honor working with a skilled professional like yourself and I hope we can work on another book in the
future. If you would like to write another book or discuss any book project, feel free to get in touch with me.
Again, many congratulations on this wonderful achievement!
The book was eventually released to the public on May 18, as a perfect 2018 birthday gift. I have gotten positive feedback and reviews from readers who have bought and read the book. The book is available on [Amazon](https://www.amazon.com/C-7-Test-Driven-Development-ebook/dp/B0772S8R7Q).
---
## Increase Your Productivity With Pomodoro Technique
URL: https://www.ayobamiadewole.com/Blog/Increase-your-productivity-with-pomodoro-technique/
Category: Others
Published: 2017-10-09
Summary: The Pomodoro Technique is a time management method: plan your tasks, break them into pieces that fit in 25 minutes, work without interruption, and take breaks between them. The author manages tasks in Todoist and often works in 1-hour cycles.
**Introduction**
Lately, I had a conversation with a developer friend on how challenging it can be as a developer having to work on multiple projects concurrently, attend meetings and responds to urgent emails and still remain productive. I mentioned to him a technique I have adopted since I was in the university and still continue to use with great success - Pomodoro Technique.
**Pomodoro Technique**
Lately, I had a conversation with a developer friend on how challenging it can be as a developer having to work on multiple projects concurrently, attend meetings and responds to urgent emails and still remain productive. I mentioned to him a technique I have adopted since I was in the university and still continue to use with great success - Pomodoro Technique.
Pomodoro technique is a time management methodology originally invented by Francesco Cirillo. He named it Pomodoro because of the shape of the timer clock (tomato shaped) that he used to keep track of his tasks. The technique involves planning at the beginning of the day what activities are to be undertaken and breaking down the tasks into smaller subtasks with assigned priority and the tasks should be completable in 25 minutes.
You should record the tasks in a to do list app or on paper if desired. I normally use Todoist a to do list and task manager for creating and managing my tasks, it is multi-platform and allows having my tasks accessible on my computers and mobile, with ability. to before selecting the topmost task or task with highest priority and set. You need to have a timer to notify you of a completion of a pomodoro, todoist paid subscription has a timer that can notify you or alternatively you can use tomato timer at [https://tomato-timer.com/](https://tomato-timer.com/)
To effectively use the pomodoro technique, you need to have breaks after each pomodoro or completion of a task which can be 25 minutes as recommended by the technique. A pomodoro should not be interrupted, but in reality there will be interruptions, these are to be recorded in the todoist app for considerations later, you have to resist the urge to stop the task you are currently working and quickly attend to the interruptions. I personally prefer and use a cycle of 1 hour after which I take 5 to 10 minutes breaks to maybe check my social media feeds, take a coffee or tea break to cool off, refresh and be active for another cycle.
**Conclusion**
Using pomodoro or any other time management technique is to effectively make you productive and get a lot done within a reasonable amount of time, for any technique to work you have to be consistent and disciplined to get desired result.
### Frequently asked questions
**What is the Pomodoro Technique?**
A time management methodology invented by Francesco Cirillo, named after the tomato-shaped timer he used. You plan the day's activities, split them into smaller prioritized subtasks that can each be completed in 25 minutes, and work through them one at a time.
**What should I do about interruptions?**
A pomodoro should not be interrupted. Record interruptions (the author logs them in Todoist) to consider later, and resist the urge to stop the current task to attend to them.
**How long should breaks be?**
Take a break after each pomodoro. The author personally prefers a cycle of one hour followed by a 5 to 10 minute break.
---
## Writing Large Datasets to Excel File using EPPlus in C#
URL: https://www.ayobamiadewole.com/Blog/How-to-write-large-dataset-to-excel-file/
Category: C#
Published: 2017-04-29
Summary: EPPlus handles very large Excel exports in C# where ClosedXML ran out of memory. In the author's test it saved 5 sheets of 1 million rows each in 61 seconds, using fewer lines of code than ClosedXML.
**Introduction**
Prior to the availability of [Open XML SDK](https://www.microsoft.com/en-us/download/details.aspx?id=30425) and other Excel libraries in . Net, manipulating Microsoft excel files from ASP.Net web applications was a daunting task. [Open XML SDK](https://www.microsoft.com/en-us/download/details.aspx?id=30425) makes it easy to manipulates documents that conforms to the Office Open XML file formats specifications with a trade-off of writing plenty lines of code. Similar to OpenXML, [ClosedXML](https://github.com/closedxml/) is another elegant library that further simplifies the process of reading and writing to excel files and hides the complexities involved, without need of dealing with XML documents.
Recently, I had to resolve an issue of a corrupt report file of an enterprise application in production. Reviewing the logs indicated that the reporting module threw a System.OutOfMemory Exception which originated from ClosedXML. The excel file being created had 5 sheets with around 400,000 rows each and ClosedXML could not handle this large amount of data.
**EPPlus**
Apparently a lot of folks have had the same issue using the library and many suggested different workaround or alternative libraries. Catching my attention from the various suggestions is [EPPlus](http://epplus.codeplex.com) library which has been around for a while but never really had much publicity like OpenXML and ClosedXML. The library is available for use via Nugget.
To test the performance and robustness of this library, I decided to throw a large dataset at it. I tried to make it create 5 sheets in a single workbook and save 1M rows in each sheet. It took 61 seconds on a DELL Latitude E5470 (Intel Core i5, 8GB RAM and 250GB SSD) for the library to process and save the records. It handled the large data graciously and also with fewer lines of codes compared to ClosedXML. See the source code below.
using OfficeOpenXml;
using System;
using System.Collections.Generic;
using System.IO;
using System.Linq;
using System.Text;
using System.Threading.Tasks;
namespace Epplus\_Poc
{
class Program
{
static void Main(string\[\] args)
{
List codeDetails = PopulateCodeDetails();
FileInfo fileInfo = new FileInfo(@"C:\\Temp\\file.xlsx");
using (ExcelPackage excelPackage = new ExcelPackage(fileInfo))
{
var workSheet = GetWorkSheet(excelPackage, 0);
var workSheet1 = GetWorkSheet(excelPackage,1);
var workSheet2= GetWorkSheet(excelPackage,2);
var workSheet3= GetWorkSheet(excelPackage,3);
var workSheet4 = GetWorkSheet(excelPackage,4);
workSheet.Cells\["B2"\].LoadFromCollection(codeDetails, false, OfficeOpenXml.Table.TableStyles.Medium1);
workSheet1.Cells\["B2"\].LoadFromCollection(codeDetails, false, OfficeOpenXml.Table.TableStyles.Medium1);
workSheet2.Cells\["B2"\].LoadFromCollection(codeDetails, false, OfficeOpenXml.Table.TableStyles.Medium1);
workSheet3.Cells\["B2"\].LoadFromCollection(codeDetails, false, OfficeOpenXml.Table.TableStyles.Medium1);
workSheet4.Cells\["B2"\].LoadFromCollection(codeDetails, false, OfficeOpenXml.Table.TableStyles.Medium1);
excelPackage.Save();
}
}
static ExcelWorksheet GetWorkSheet(ExcelPackage excelPackage, int count)
{
var workSheet = excelPackage.Workbook.Worksheets.Add("Content - "+count);
workSheet.View.ShowGridLines = false;
workSheet.Cells\["B1"\].Value = "Code";
workSheet.Cells\["C1"\].Value = "Time";
workSheet.Cells\["D1"\].Value = "Date";
workSheet.Cells\["B1:D1"\].Style.Font.Bold = true;
return workSheet;
}
public static List PopulateCodeDetails()
{
List codeDetails = new List();
Random random = new Random();
for(int i=1; i<=1000000; i++)
{
CodeDetail codeDetail = new CodeDetail();
codeDetail.Code = random.Next(12324343).ToString();
codeDetail.Time = DateTime.Now.ToShortTimeString();
codeDetail.Date = DateTime.Now.ToShortDateString();
codeDetails.Add(codeDetail);
}
return codeDetails;
}
}
public class CodeDetail
{
public string Code { get; set; }
public string Time { get; set; }
public string Date { get; set; }
}
}
When next you need to process large dataset and save it to Excel file, you can try EPPlus library.
### Frequently asked questions
**Why did ClosedXML fail on a large report?**
In the author's production case the reporting module threw a System.OutOfMemoryException that originated from ClosedXML. The workbook had 5 sheets of around 400,000 rows each, and the report file ended up corrupt.
**How well does EPPlus handle large datasets?**
In the author's test on a Dell Latitude E5470 (Core i5, 8GB RAM, SSD), EPPlus created one workbook with 5 sheets of 1 million rows each and saved it in 61 seconds, with fewer lines of code than ClosedXML.
---
## Pdf Conversion to Image Using MagickNet in C#
URL: https://www.ayobamiadewole.com/Blog/Pdf-Conversion-to-Image-Using-MagickNet-in-Csharp/
Category: C#
Published: 2016-12-01
Summary: Magick.NET, a .NET wrapper around ImageMagick, can convert every page of a PDF to images in C# as long as Ghostscript is installed on the server. Point MagickNET at the Ghostscript path and set a temp folder.
**Introduction**
Sometimes back, I worked on an asp.net MVC application which had a feature request to support conversion of pdf documents to images to allow viewing of the documents on devices that have Javascript disabled and most likely do not have native pdf reader app installed.
Initially, I thought of developing a custom library for this, but could not due to tight deadline of the project. I decided to search Nugget Gallery for hosted libraries that can be used for this purpose, but most of the libraries available on Nugget are limited in functionalities and not usable.
Searching [codeplex.com](https://www.codeplex.com), I came across Magick.net, [https://magick.codeplex.com](https://magick.codeplex.com) an image processing library built as a wrapper on ImageMagick which can also convert pdf files to images if Ghostscript is installed on the application server. Ghostscript can be downloaded at [http://www.ghostscript.com/download/gsdnld.html](http://www.ghostscript.com/download/gsdnld.html)
The PdfToImageConverter class I wrote for the pdf to image conversion is explained below. Once Ghostscript is installed, MagickNET needs to be aware of the installation path and also a Temp folder needs to be set as it writes some temporary files to disk. The library can read pdf file of any size and convert all the pages in the file to images and save the converted images to the path specified in the method parameter.
See the source listing of the PdfToImageConverter class below.
public class PdfToImageConverter
{
public PdfToImageConverter(string filePath)
{
MagickNET.SetGhostscriptDirectory(filePath+"Lib");
MagickNET.SetTempDirectory(filePath + "\\Temp");
}
public int ConvertFileToImages(string filePath, string destinationPath)
{
int noofPages = 0;
MagickReadSettings magickReadSettings = new MagickReadSettings();
magickReadSettings.Density = new Density(300, 300);
using (MagickImageCollection magickImageCollection = new MagickImageCollection())
{
magickImageCollection.Read(filePath, magickReadSettings);
int page = 1;
noofPages = magickImageCollection.Count;
foreach (MagickImage magickImage in magickImageCollection)
{
magickImage.Format = MagickFormat.Png;
string imageFilePath = string.Concat(destinationPath,"file-", page, ".png");
magickImage.Write(imageFilePath);
page++;
}
}
return noofPages;
}
}
### Frequently asked questions
**How do I convert a PDF to images in C#?**
Use Magick.NET, an image processing library built as a wrapper on ImageMagick. It can read PDF files of any size and convert all their pages to images saved to a path you specify, provided Ghostscript is installed on the application server.
**What setup does Magick.NET need to handle PDFs?**
Once Ghostscript is installed, MagickNET has to be told its installation path, and a temp folder must be set because the library writes temporary files to disk.
**Why convert PDFs to images at all?**
The author needed it so documents could be viewed on devices that have JavaScript disabled and likely have no native PDF reader app installed.
---
## Importing Excel File with SheetJs in Asp.net MVC
URL: https://www.ayobamiadewole.com/Blog/Importing-Excel-File-with-SheetJs/
Category: Asp.Net
Published: 2016-02-19
Summary: SheetJS parses Excel files in the browser and converts them to JSON or CSV, so a bulk-import feature can post the data to the server by Ajax without server-side Excel parsing. The ASP.NET MVC example deserializes the JSON with Json.NET.
**Introduction**
I recently worked on a project with a feature requirement to allow bulk import of data from Microsoft Excel files. My choice of framework to use would have been either [Open XML SDK](https://www.microsoft.com/en-us/download/details.aspx?id=30425) or [LinqToExcel](https://github.com/paulyoder/LinqToExcel) because I have used both libraries in the various projects in the past and they performed well. But common we are in 2016, I wanted to try out a new library. I asked a programmer friend, [Ahmed Opeyemi](http://ahmedopeyemi.com) if he has used any library lately and he recommended [SheetJs.](https://github.com/SheetJS/js-xlsx) I decided to do some check on the library to see if it will meet my requirement.
**SheetJS**
After reading the library’s online documentation on [Github](https://github.com/SheetJS/js-xlsx), I like the fact that it can convert the data extracted from the excel file to CSV or JSON or even generate a list of formulae from the excel file being parsed. The generated data that can later be uploaded to the server by an Ajax Post. Also, since the extraction and JSON conversion is done directly on the user's browser it frees the server of the processing that hitherto would have been done on it.
**Building the application**
Navigate to [https://github.com/SheetJS/js-xlsx](https://github.com/SheetJS/js-xlsx) to download the library and include the xlsx.core js library in the view where you want the data upload feature
I decided to handle the onchange event of the html file input so that whenever the user selects the excel file, the data contained therein can be extracted and posted to the server through.
The code snippet for performing the excel file parsing and uploading it to the server is as shown below
The portion of codes below does the magic of extracting the data from the excel file.
var workbook = XLSX.read(data, { type: 'binary' });
var result = {};
workbook.SheetNames.forEach(function (sheetName) {
var roa = X.utils.sheet\_to\_row\_object\_array(workbook.Sheets\[sheetName\]);
if (roa.length > 0) {
result\[sheetName\] = roa;
}
});
And to deserialize the JSON data to a list of .net object , I use the popular [Json.NET](http://www.newtonsoft.com/json) library. The code of the ActionResult method in the Controller class is below
\[HttpPost\]
public ActionResult DataUpload(FormCollection formCollection)
{
string dataToUpload = formCollection\["dataToUpload"\];
int recordsUploaded = 0;
GroupDTO groupDTO = JsonConvert.DeserializeObject(dataToUpload);
// do something with the data
return Json(new { records = string.Concat(“Total records”, recordsUploaded)});
}
The GroupDTO class definition is below
public class GroupDTO
{
public List Data { get; set; }
public long ChurchId { get; set; }
}
public class GroupJson
{
public string Name { get; set; }
public string Description { get; set; }
}
And that is it, you have the data extracted and uploaded with little work at the server end.
### Frequently asked questions
**Why parse Excel files in the browser with SheetJS?**
The extraction and JSON conversion happen in the user's browser, which frees the server of that processing. SheetJS can also output CSV or a list of formulae from the file.
**How does the upload work in the ASP.NET MVC example?**
The page handles the file input's onchange event, extracts the data from the chosen Excel file as JSON in the browser, and posts it to a controller action by Ajax, where Json.NET deserializes it into a list of .NET objects.
---
## How to Provision Cisco IP Phones 8861, 7861,7821,7811 and 7942G for use with Freeswitch PBX
URL: https://www.ayobamiadewole.com/Blog/How-to-provision-Cisco-IP-Phones-for-use-with-Freeswitch/
Category: VoIP
Published: 2015-11-16
Summary: Cisco IP phones ship configured for Cisco Unified Communications Manager (SCCP), so using them with FreeSWITCH means upgrading their firmware to SIP from a TFTP server, with XML config files. The post covers the 8861, 7861, 7821, 7811 and 7942G.
**Introduction**
Using soft phones with Freeswitch PBX allows the utilization of existing PCs or smart phones as the communicating devices. But often there are times when the requirements for setting up or deploying a Unified Communication solution necessitate the use of IP phones. Freeswitch has been tested and works well with various IP phones, more details can be found at [https://freeswitch.org/confluence/display/FREESWITCH/Phones](https://freeswitch.org/confluence/display/FREESWITCH/Phones) In this blog post I will explain how I got five different models of Cisco IP phones provisioned for use with Freeswitch.
Cisco IP phones are factory configured or provisioned to work only with Cisco Unified Communication manager which mainly uses SCCP as communication protocol. Freeswitch supports SCCP though, but to enable the IP phones work seamless with Freeswitch, the firmwares on the various phones need to be upgraded to enable them use SIP and subsequently provisioned while doing the upgrade.
**Required Tools**
Cisco IP phones usually will get their firmware upgrade from a TFTP server residing on the network. Newer models of Cisco phones allow manually inputing IP address of the TFTP server in the phone configuration. But for the old model; 7942G, the DHCP server will have to advertise the address of the TFTP server to it.
**On a Windows PC** Tftpd32 is an utilitiy app that will make aWindows PC serve as both the DHCP and TFTP server at the same time, it can be downloaded from.
**On a Linux PC** I did the provisioning 8861, 7861,7821,7811 models on a Debian PC. First install the tftp application running this command on the terminal.
apt-get install atftpd
Then run vi /etc/default/atftpd to edit the content of atftpd by adding – port 69 to the content of the file to make it look like what is shown below
USE\_INETD=false
OPTIONS="--port 69 --tftpd-timeout 300 --retry-timeout 5 --mcast-port 1758 --mcast-addr 239.239.239.0-255 --mcast-ttl 1 --maxthread 100 --verbose=5 /srv/tftp"
Save the file and exit vi. Start the tftp server by running this command
/etc/init.d/atftpd start
To allow connection to be made to the tftp server on port 69 run the command below, while substituting the IP for your network IP
iptables -A INPUT -p udp -s 172.16.20.0/24 -m multiport --dport 69 -m state --state NEW -j ACCEPT
I recommend downloading firmware files for the phones directly from Cisco software download center, you can register an account which will be verified and will allow you to download the SIP upgrade files. After downloading the files, you should extract and copy the contents to the tftp server root folder.
**Firmware Upgrade and Provisioning**
Before the upgrade can be done, some required xml files need to be created and placed in the tftp server root folder.
**Diaplan.xml**
The content of the diaplan.xml file is to tell the phone the pattern in which the phone number will take.
**XMLDefault.cnf.xml**
200024272428172.16.20.15sip88xx.10-3-1-20
This configuration file contains description of the version of the fimware that the phone should request from the TFTP server and the address of the PBX server. Change the value in the bolded elements to match the IP address to your PBX server and the version of the firmware.
**SEPxxxxxx.cnf.xml**
A copy of this file will be created in the TFTP root folder for each of the IP Phones to be provisioned, the format for naming the file is SEP\[MAC of Phone\].cnf.xml eg SEP054B443C44.cnf.xml. The content of the usually looks like what is shown below
SIPciscociscoD/M/YaUTC+01:00 Standard/Daylight Time172.16.20.15Unicast200050605061172.16.20.15truetruex-serviceuri-cfwdallx-cisco-serviceuri-pickupx-cisco-serviceuri-opickupx-cisco-serviceuri-gpickupx-cisco-serviceuri-meetmex-cisco-serviceuri-abbrdialfalse2truetrue220true610180360051201205500400070trueNone1falsetruefalsefalseg711ulaw1013avtfalsefalse3false2080false10false16384327669ReceptionUSECALLMANAGER506020820823208\*1234#false1350145208truetruefalsetrue50601840dialplan.xmltrue1sip88xx.10-3-1-20falsefalse0100000220111143565489-a3cbf294-7526-4c29-8791-c4fce4ce4c37USUS5.0(2)196096203804false
You can change the values of the elements of the xml configuration file to reflect your PBX installation and save the files.
For newer models of Cisco IP phones in which the IP address of the TFTP server can be manually entered into the phone, follow this step to input the TFTP Server address.
Press the menu key on the phone then press Admin Settings -> Network Setup -> Ethernet Configuration -> IPV4 Setup -> Alternate TFTP Server -> TFTP Server 1
Once the file has been saved, power cycle the IP Phone in which the configuration file was jut created by removing the Rj45 cable from the POE switch and plug it back while holding the # key on the phone, when the light comes on the display press 1234567890\*# this will start the upgrade process for the phone.
**Provisioning 7942G**
**Updated 06/01/2016**
Provisioning 7942G model of Cisco IP phones takes a different approach, because manual input of TFTP server IP address has been disabled, press **\*\*#** to unlock the manual input screen. Then follow the steps mentioned earlier to reset or power cycle the phone.
An approach earlier used before the update posted above is to use a utility; tftpd as explained in the way I earlier got the phone configured below. I took the 7942G phones off the general network and placed on a private local network with no DHCP server, I used the Tftpd32 utility on a Windows PC to make the PC both the DHPC and the TFTP server and assigned a static IP address to the PC as shown in the picture below.


You should point the tftpd application to the location of the sip upgrade files on the windows PC. You can then power cycle the IP Phones has described earlier, the phones will be assigned IP address by Tftpd32 application and the phone will start the upgrade, you will see on the application log as the files are being sent to the phone as shown in the screen below.

8861 Model

7861 Model

7821 Model

7811 Model

7942G Model

### Frequently asked questions
**Why must Cisco IP phones be upgraded to work with FreeSWITCH?**
They are factory configured to work only with Cisco Unified Communications Manager, which mainly uses SCCP. FreeSWITCH supports SCCP, but for the phones to work seamlessly with it their firmware needs to be upgraded to use SIP.
**What is needed to do the upgrade?**
A TFTP server on the network that serves the firmware, plus XML files in its root folder: diaplan.xml (the phone number pattern), XMLDefault.cnf.xml (the firmware version to request and the PBX address) and one SEP[MAC address].cnf.xml file for each phone.
**How does the 7942G differ from newer models?**
Newer models let you enter the TFTP server address manually on the phone. The post originally said the older 7942G needed the DHCP server to advertise it; its 2016 update says pressing **# unlocks the manual input screen on the 7942G.
---
## How to build FreeSwitch on Debian 8 (Jessie)
URL: https://www.ayobamiadewole.com/Blog/How-to-build-FreeSwitch-on-Debian-Jessie/
Category: VoIP
Published: 2015-08-31
Summary: Steps to build FreeSWITCH from source on a fresh Debian 8 (Jessie) install so you can enable the modules you need: add the FreeSWITCH repository, install dependencies, clone the source, edit modules.conf, build, set kernel options and enable the systemd service.
**Introduction**
FreeSwitch is an open source telephony platform, with support for multiple protocols (SIP, IAX, Googletalk, Jabber, XMPP, WOOMERA/H.323, PRI/T1/E1) and it is cross platform (Linux, Windows and Mac). It is a softswitch which implies that it does the job of a traditional PBX and much more. It is scalable and has been tested to handle thousands of simultaneous calls. It is fully extendable and can be customized to meet customers VOIP needs.
FreeSwitch pre-built binaries packages are available for download for installation Linux, Windows and Mac, with minimal modules included to get it running. But to harness the power of FreeSwitch with the various modules it has, FreeSwitch needs to be built from source with the option of enabling the modules required for your custom PBX setup.
FreeSwitch development team recommends Debian as the operating system of choice, starting from FreeSwitch 1.6 a number of libraries required to build Freeswitch are included in Debian 8, this blog post will run through steps involved to build Freeswitch on a fresh installation of Debain 8 (Jessie).
**Debian 8 Installation**
Download and install Debian 8 installation packages from the following link. [http://cdimage.debian.org/debian-cd/8.1.0/amd64/iso-dvd/](http://cdimage.debian.org/debian-cd/8.1.0/amd64/iso-dvd/). Run through the installation process and set the server up accordingly. After the installation is completed, edit the **/etc/apt/sources.list** file, add # to comment out the dvd source in the file to prevent apt-get from requesting to get packages from the dvd path. Uncomment the other download sources and add the mirror **deb http://http.us.debian.org/debian jessie main contrib** and save the file. Run the command below to download available updates and upgrade the pc with the latest available libraries.
sudo apt-update && apt-upgrade
**Preparing to Build FreeSwitch**
All commands to be run on the terminal should be run using **root** account to ensure that required permissions and priviledges are granted.
FreeSwitch Debian Jessie repository needs to be enabled, the commands below will create 99FreeSWITCH.test.list file and add it to **/etc/apt/sources.list.d** folder and also download and add a GPG key to the apt sources keyring.
echo "deb http://files.freeswitch.org/repo/deb/debian/ jessie main" > /etc/apt/sources.list.d/99FreeSWITCH.test.list
wget -O - http://files.freeswitch.org/repo/deb/debian/key.gpg |apt-key add -
apt-get update
Next, download the needed dependecies to build FreeSwitch using this command
DEBIAN\_FRONTEND=none APT\_LISTCHANGES\_FRONTEND=none apt-get install -y --force-yes freeswitch-video-deps-most
Now, the source code will be cloneed from repository.
cd /usr/src/
git config --global pull.rebase true
git clone https://freeswitch.org/stash/scm/fs/freeswitch.git freeswitch.git
cd /usr/src/freeswitch.git
**Building FreeSwitch** After the Freeswitch source has be cloned from the repository, edit modules.conf file inside the freeswitch source folder to enable specific modules needed for your Freeswitch installation. Then run the following commands
./bootstrap.sh -j
./configure -C
make
make install
make cd-sounds-install
make cd-moh-install
make samples
You might be tempted to run FreeSwitch immediately the after the make and install. But hold on, few configurations need to be done.
Edit the System Kernel setting file **/etc/sysctl.d/vid.conf** and add the following lines.
net.core.rmem\_max = 16777216
net.core.wmem\_max = 16777216
kernel.core\_pattern = core.%p
Next, activate the kernel settings changes earlier made by running the following commands.
sysctl -w net.core.rmem\_max=16777216
sysctl -w net.core.wmem\_max=16777216
sysctl -w kernel.core\_pattern=core.%p
Remember earlier, I said all commands should be run as super user, this implies that FreeSwitch was built as root. To allow system to system to interact with FreeSwitch, a user ‘freeswitch’ will be created and put in group ‘daemon’ and we will change the ownership of the FreeSwitch installation folder and the containing to the user ‘freeswitch’ to be created. Run the following commands on the terminal
cd /usr/local
adduser --disabled-password --quiet --system --home /usr/local/freeswitch --gecos "FreeSWITCH" --ingroup daemon freeswitch
chown -R freeswitch:daemon /usr/local/freeswitch/
chmod -R ug=rwX,o= /usr/local/freeswitch/
chmod -R u=rwx,g=rx /usr/local/freeswitch/bin/\*
Freeswitch source comes with a systemd file which when configured properly will at boot time, monitor the Freeswich to start it as a daemon, restart it if it fails. The file can be found in this location **usr/src/freeswitch.git/debian/freeswitch-systemd.freeswitch.service** you can change the con-tent to reflect the path to your freeswitch installation.
Lets link the systemd unif file above to systemd using this command
ln -s /usr/src/freeswitch.git/debian/freeswitch-systemd.freeswitch.service /etc/systemd/system/freeswitch.service
Next, run the following command systemctl daemon-reload to notify systemd to reload and look for changes in its configuration. Now run **systemctl enable freeswitch** to install FreeSWITCH to start at boot time.
To start Freeswitch for the first time run this command
systemctl start freeswitch
Freeswitch comes with a Command Line Interface program that can be used to to interact and send commands to Freeswitch . **/usr/local/freeswitch/bin/fs\_cli –l 6**
And that is it, you have FreeSwitch built and configured.
### Frequently asked questions
**Why build FreeSWITCH from source?**
The pre-built binary packages include only a minimal set of modules. Building from source lets you enable the modules your custom PBX setup needs.
**Which operating system is recommended?**
The FreeSWITCH development team recommends Debian. Starting with FreeSWITCH 1.6, a number of the libraries required to build it are included in Debian 8.
**How do I start FreeSWITCH and reach its command line?**
Link the bundled systemd unit file, run systemctl daemon-reload and systemctl enable freeswitch, start the service, then use the CLI program /usr/local/freeswitch/bin/fs_cli.
---
## Code Quality Metrics with NDepend
URL: https://www.ayobamiadewole.com/Blog/Code-Quality-Metrics-with-NDepend/
Category: Others
Published: 2015-04-30
Summary: NDepend is a code quality tool that integrates with Visual Studio: attach it to a solution, run the analysis, and view metrics such as lines of code, rule violations and cyclomatic complexity on its dashboard, in a treemap, or in a browser.
**Introduction**
The quality of a software application can be determined by the quality of the codebase. Code quality analysis as over the years become an integral part of software development process, this is to ensure that developers follow best practices while writing codes to ensure that codebase is maintainable, reusable and also to determine portion or section of codes that are problematic and might be candidate for refactoring if need be.
Code metrics usually entails measuring code complexities, lines of code (LOC) or kilo line of codes (KLOC), cyclomatic complexity, coding styles/rules violation and other constraints. These can give great insight into the software applications being developed. Code metrics are usually generated with the use of code analysis tools.
**NDepend**
NDepend is a code quality analysis tool that when installed integrates into Microsoft Visual Studio and can be used to generate code metrics for projects in a solution and it gives meaningful and detailed reports in a well formatted way with charts and graph. NDepend can be downloaded at [http://www.ndepend.com/](http://www.ndepend.com/).
Generating code metrics for projects in a solution is by attaching NDepend to the solution. After the installation of NDepend, a new menu is added to Visual Studio’s menus as shown in the screen below
Attaching NDepend to an existing project brings out a dialog box like the one shown below, indicating all the projects in the concerned solution. Assemblies can also be added by dragging and dropping from windows explorer to the NDepend dialog box to analyze after which the analyze button is clicked.

NDepend will run the analysis and save the result of the analysis in an NDependOut folder that would be created in the solution folder of the project after which a dialog box would be displayed as shown below, the results of the analysis can be viewed from the NDepend's Dashboard.
On the dashboard, the code metrics analysis generated for the solution can be viewed containing detailed reports with information such as the lines of codes, code rules violated, method complexities and so on. Viewing the metrics report is not limited to the dashboard on visual studio alone, the reports can also be viewed from the browser.
Treemap metric view is also available from the NDepend dashboard

Cyclomatic code complexity analysis can give an insight on how complex a project is, NDepend thrives well in this by giving detailed analysis of cyclomatic complexity of classes and the methods cotained like the one shown in screen below.
NDepend gives detailed metrics reports of projects in a solution. It is a productivity tool I have come to fancy overtime.
---
## Dealdey.com "Get an iPhone6 for just 40K" Scam
URL: https://www.ayobamiadewole.com/Blog/Dealdey-Iphone-6-Scam/
Category: My Views
Published: 2015-03-06
Summary: From 2015: the author alleges that Dealdey.com's "iPhone 6 for 40K" deal was not genuine. A console program they wrote to watch the site alerted them when the deal appeared at 4:31 pm, but the phones were already sold out. Includes the C# source, which uses HtmlAgilityPack.
**Introduction**
It is so unfortunate how E-Commerce shops in Nigeria the likes of **Dealdey.com** **Jumia.com** and the rest scam Nigerians by offering ridiculous price for items which they don't have in stock in a bid to get traffic to there site and often rip customers off. Ironically, they don't have the infrastructure to handle the resulting traffic as can be seen by the outage of service on their websites.
**Dealdey.com Iphone 6 Scam**
Latest is the Dealdey.com **"Get an iPhone6 for just 40K"** scam today 05/03/2015. when my colleagues and I saw the advert on the dealdey.com, we were very sceptical about it due to our earlier experience with Jumia.com on Black Friday of 2014 in which we purchased items and made online payments, our accounts were debited but we didn't receive the items purchased and no refund was made ever since.
The Dealdey.com ridiculous scam of "Get an iPhone6 for just 40K" prompted us to quickly develop a small console program to monitor their website to check and notify us whenever the iphone 6 is made available. The program checks www.dealsdey.com/deals and looks for the keyword iphone-6 and if found makes a long beep, if not it should keep checking after a set interval.
The program ran on a pc with Etisalat broadband 3.5G internet connection from 11:30am when the deal was supposed to start till 4:31 pm when Dealdey.com finally put the deal online. The moment we were notified of the link (by our app), We quickly navigated to the Url to check out the deal, only to be told that all Iphone 6 phones have been sold out.

From my calculation it took less than 10 seconds after the link appeared on Dealdey.com site for my browser to load the url.
My question now which I hope dealdey would provide answers to include:
1. How many Iphones were up for grab that it was sold off under 10 seconds?
2. Why the change in time of the post of the deal?
Their actions would suggest that they never planned to sell any iphone nor do they have any iphone in stock. They just used it to lure innocent Nigerians into shopping on their platform.
E-Commerce shops/sites in Nigeria should desist from scamming innocent Nigerians, by putting promos or deals that dont exist.
Below is the C# source code of the utility program, it uses HtmlAgilityPack for the html dom manipulation.
private static void Main(string\[\] args)
{
string url = "http://www.dealdey.com/deals";
startover:
try
{
int iphoneCount = 0;
while (iphoneCount < 1)
{
Console.WriteLine("Connecting to " + url+"\\n");
HtmlWeb htmlWeb = new HtmlWeb();
HtmlDocument htmlDocument = htmlWeb.Load(url);
Console.WriteLine("Connected to " + url);
foreach (HtmlNode htmlNode in htmlDocument.DocumentNode.SelectNodes("//a\[@href\]"))
{
HtmlAttribute htmlAttribute = htmlNode.Attributes\["href"\];
if (htmlAttribute.Value.Contains("iphone-6"))
{
iphoneCount++;
Console.WriteLine("Link found\\n");
Console.WriteLine(htmlAttribute.Value);
}
}
if (iphoneCount < 1)
{
Thread.Sleep(10000);
Console.Clear();
iphoneCount = 0;
}
else
{
break;
}
}
Console.WriteLine("Iphone is available \\n");
Console.Beep(500, 5000);
Console.ReadLine();
}
catch(Exception e)
{
Console.WriteLine("Encountered Error, Starting Over Again \\n");
goto startover;
}
}
---
## Running Large Sql Script in Microsoft Sql Server
URL: https://www.ayobamiadewole.com/Blog/Running-Large-Sql-Script-in-Microsoft-Sql-Server/
Category: Others
Published: 2015-02-16
Summary: Use sqlcmd, the command-line tool that ships with SQL Server, to run script files too big to open in Management Studio. Pass the server, database, script path, log file and packet size, and use a hex editor to inspect the file.
#### Introduction
Running large sql script file, such as database dump of applications already in production is not a trivial endeavor usually because of the size of the sql script files and the time it takes to complete the execution.
#### sqlcmd Utility
The size of such files usually run into several gigabytes, if not terabytes of data, such files cannot be opened directly in Microsoft Sql Server Management Studio or any readily available text editors because of memory constraint.
Microsoft Sql Server ships with sqlcmd utility, a command line tool for executing Transact-SQL statements as well as executing script files. Sqlcmd can be used to run large script files that Sql Server management studio would not be able to open.
Sqlcmd accepts several command line options to allow easy customization of the process, for the sake of brevity, only the options used in this blog post are explained below.
\-S server instance
-d Database name
-I path to the script to be executed
-o path to where the log would be written to
-a packet size
A regular command to execute a script file with sqlcmd would look like this
sqlcmd -S Ayobami-Pc -d Tap -i C:\\Backup\_production\\script.sql -o C:\\Db\\output.log -a 32767
Where Ayobami-PC is the server instance, C:\\Backup\_production\\script.sql is the path to the script file to be executed, C:\\Db\\output.log is the path to the log file and 32767 is the packet size.
There might be need to examine the script file and edit the content before executing, conventional text editors would not be able to open the file, there is an open source tool suitable for this, [Free Hex Editor](http://www.hhdsoftware.com/free-hex-editor), another editor is **EmEditor** although it is not free, also works fine.
More information on sqlcmd can be found at [MSDN](https://msdn.microsoft.com/en-us/library/ms162773.aspx).
### Frequently asked questions
**How do I run a multi-gigabyte SQL script file?**
Use sqlcmd. The file is too large to open in SQL Server Management Studio or a normal text editor because of memory constraints, but sqlcmd executes script files directly from the command line.
**What does a sqlcmd command for a large script look like?**
sqlcmd -S Ayobami-Pc -d Tap -i C:\Backup_production\script.sql -o C:\Db\output.log -a 32767, where -S is the server instance, -d the database, -i the script file, -o the log file and -a the packet size.
**How can I view or edit a script that large?**
Conventional text editors cannot open it. The post suggests Free Hex Editor, which is open source, or EmEditor, which works well but is not free.
---
## Capturing Webpage Screenshot with Html2Canvas.js
URL: https://www.ayobamiadewole.com/Blog/Capturing-Webpage-Screenshot-with-Html2Canvas/
Category: Asp.Net
Published: 2015-01-31
Summary: Html2canvas.js captures a page screenshot in the browser by traversing the DOM and rebuilding the page, with its images and CSS, on a canvas. The post uses it in ASP.NET MVC to capture a submitted form and upload the image as a PNG.
#### Introduction
Recently, I was to implement a web application requirement that stipulates that the screenshot of a web page containing form filled by users be captured, as the form is being submitted. While this may seems trivial, a lot of intricacies is involved in building an image representation of the page as it is shown on the browser.
#### Html2canvas.js
Html2canvas.js is a javascript library that provides functionality for capturing a screenshot, the screenshot is built based on the information available on the page. The script traverses the DOM and builds a representation of the page alongside the images and the css styles present on the page, but it doesn’t render flash, java applets and iframe. The html2canvas library can be downloaded [here](https://github.com/niklasvh/html2canvas/releases)
The example in this blog post uses Asp.net MVC and it contains code to capture the screenshot and display the captured image on the browser and upload the image to the controller action method for saving as a png file on the server.
Add reference to the required javascript libraries at the header of the page
Below is the Razor and Html tags for the page
@using(Html.BeginForm("ScreenShot", "Home", FormMethod.Post, new { @id = "form" }))
{
Some text that would be captured as screenshot
@Html.Hidden("capturedShot")
}
The javascript code for capturing the screenshot and displaying the captured image and that for uploading to the server.
The controller action method below accepts the uploaded screenshot and writes it to a file.
\[HttpPost\]
public ActionResult ScreenShot(FormCollection formCollection)
{
string screenShot = formCollection\["capturedShot"\];
//remove the image header details
string trimmedData = screenShot.Replace("data:image/png;base64,","");
//convert the base 64 string image to byte array
byte\[\] uploadedImage=Convert.FromBase64String(trimmedData);
//the byte array can be saved into database or on file system
//saving the image on the server
string fileName=Guid.NewGuid()+".png";
string path=Server.MapPath("~/App\_Data/"+fileName);
System.IO.File.WriteAllBytes(path,uploadedImage);
return View();
}
### Frequently asked questions
**How does html2canvas capture a screenshot?**
It does not take a true screenshot. The script traverses the DOM and builds a representation of the page from the information available on it, along with the images and CSS styles present.
**What can't html2canvas render?**
It does not render Flash, Java applets or iframes.
**How is the captured image saved in the ASP.NET MVC example?**
The screenshot is displayed in the browser and uploaded to a controller action method, which writes it to a PNG file on the server.
---
## Data Migration
URL: https://www.ayobamiadewole.com/Blog/Data-Migration/
Category: Others
Published: 2015-01-25
Summary: Data migration moves data between storage, databases or applications and follows four phases: assessment, planning, migration and validation. Best practices include replicating data first, planning downtime, validating accuracy and documenting everything.
### Introduction
Data migration is the process of transferring data from one system to the other, which can necessitate changing the storage type, formats, database, application or computer systems.
Reasons for embarking on a data migration project might be due to a need to upgrade hardware platforms or servers, change of storage equipment, database upgrade or migration to a new software application. It is a complex undertaking and it’s a branch of IT in which the processes and software tools being used are continually evolving.
Making mistakes in a data migration project can lead to loss of data and this might be very costly for a business and organization embarking on the project. Nonetheless, if choices are made carefully and the project is adequately planned, the migration project would be completed in a timely manner without any problem afterwards.
Data Migration can be in the form of
* **Storage Migration**: with the current advancement in storage technologies, it is not uncommon for businesses to choose to take advantage of more efficient and effective storage technologies, thus, moving data from one hardware storage platform to another, which can be local disk, iSCSI or Fibre Channel (FC). This would necessitate the movement of blocks of data from one storage medium to another, the format of the data is usually not changed in this process.
* **Database Migration**: this is the most common form of migration, it entails the upgrade of a database version or moving from one database vendor to another. A database migration project might lead to change in the data format which may or may not affect the behavior of the application and as such a validation process is required at the end of the migration procedure. A vendor change can be from Mysql, Sybase or Oracle to SQL Server.
* **Application Migration**: every software application has, and can operates its own specific data model or schema, changing the application vendor can trigger a migration project, say changing a business’ ERP vendor from SAP to Sage will definitely require migration of the data from the existing application to the new application. Application migration can also be in the form of application environment change such as moving an application from an on premise server to a cloud provider’s environment.
### Data Migration Methodology
Data migration usually involves four steps or processes

**Assessment**: this phase involves information gathering about the migration environment, a thorough assessment of the data to be migrated, its current format and the new format it will take after migration, risks assessment is also done to evaluate any challenges that might be faced in the process. At the end of this phase, a report is usually generated to determine the cost, risks and time frames of the migration.
Checklist
* Evaluate and analyze the data to be migrated
* Evaluate the current and future environments
* Define appropriate standards
**Planning**: this process usually involves the determining the migration requirements, time schedules, while identifying the current and future environments. At the stage, the hardware or software needed to successfully carry out the migration is identified. It is a good practice for the IT staff to carry the business owners along in the planning process, this might help determine potential problems.
Checklist
* Document Plan
* Notify users of the migration schedule
* Set a realistic time frame
* Prepare a test plan
**Migration**: This is the actual migration phase also known as “Move”, at the stage the IT staff(s) involved in the migration would configure the software tools and or hardware required for the migration. Software tools can speed up the process while reducing or eliminating business downtime.
Checklist
* Revise migration plan
* Configure migration environment
* Perform backup or replication of data to be migrated
* Initiate migration process
* Prepare migration report
**Validation**: data validation is required upon completion of the migration to ensure the integrity of the data. A migration statistics and reports should be prepared, this should include what worked and what didn’t during the migration. The steps used in the migration should be duly documented to simplify future migrations of the same pattern. Acceptance testing should be done by the business owners. Verify database schema and validate that the data was migrated correctly
Checklist
* Test data to ensure integrity
* Perform roll back if data corruption occurs
### Choosing appropriate data migration software
The choice of the migration software should take into consideration the OS environments, source and target hardware platforms and the database vendors and versions in the case of a database migration project.
A key requirement to consider is the ability to roll back the migration should in case something goes wrong. This is a great concern in the eventuality of a problem or an error, the migration software should be able to terminate, restart or roll back entirely the process.
The performance of the software should be considered when making choice, how quickly the data is copied from the source environment to the target environment. Performance should be balanced against system overhead and network bandwidth.
**Storage Migration software tools**
* Rsync: its open source and provides fast incremental file transfer.
* IBM Softek Transparent Data Migration Facility can migrate data at the volume or block level, supports multiple platforms.
* SanXfer: can migrate server data volumes and is optimized for cloud environments.
* Hitachi Data Systems Universal Replicator: provides storage array-based replication.
**Database Migration software tools**
Most database vendors ship migration tools with their products, nevertheless, there are some readily available commercial software tools
* Microsoft SQL Server Migration Assistant (SSMA) for migrating MySQL or Oracle database to SQL Server.
* MySQL Workbench Wizard for easy database migration to MySQL.
* Oracle SQL Developer provide tool for migrating non Oracle databases to Oracle.
* EDB Migration Toolkit for database migration to Postgres.
* There are other commercial products used for database migration such as Flyway, SwisSQL, ESF Database Migration Toolkit, Ispirer’s SQLways
**Application Migration Software tools**
Application migration is usually complex and complicated and as such application vendors normally provide custom tools to migrate data from one application to the other,
### Data Migration Best Practices
* Migration projects are time consuming and as such a proper planning is crucial to the successful implementation of the project.
* It is important to understand the data being migrated, the current and future storage as well as the current and future form or format.
* A duplication or replication of the data is advised before migration. Implement data migration policies so data is moved in an orderly manner.
* A proper shutdown or downtime plan should be put in place for duration of the migration project, with which the business would not have access to the data.
* Accuracy of the migrated data should be ensured using test and validation procedures.
* Adequate documentation of the entire process could simplify related future projects.
### Conclusion
Data migration is often a very complex process, thus a good working cooperation is required among the IT staffs, the business owners and any stakeholder involved in the migration. Following best practices and choosing the suitable software for the project can facilitate smooth and timely completion of the project.
### Frequently asked questions
**What are the types of data migration?**
Storage migration (moving data between storage platforms), database migration (upgrading a database version or switching vendors, the most common form) and application migration (for example, changing ERP vendor from SAP to Sage).
**What are the phases of a data migration project?**
Four: Assessment (gather information, assess the data and risks), Planning (requirements, schedule, tools and a test plan), Migration (configure tools, back up or replicate the data, run the migration and report) and Validation (test data integrity, roll back if data is corrupted, and document the process).
**What are the best practices for data migration?**
Understand the data and its current and future formats, duplicate or replicate the data before migrating, put a downtime plan in place, verify the accuracy of the migrated data with tests, and document the entire process.
**What should I consider when choosing migration software?**
The operating system environments, the source and target hardware platforms, and database vendors and versions. Also the ability to roll back if something goes wrong, and performance balanced against system overhead and network bandwidth.
---
## Bulk Data Insertion into Oracle Database in C#
URL: https://www.ayobamiadewole.com/Blog/Bulk-Data-Insertion-into-Oracle-Database-in-Csharp/
Category: C#
Published: 2015-01-18
Summary: To bulk insert records into an Oracle table from C#, use ODP.NET's array binding: put the values in arrays and pass them to OracleCommand, instead of inserting row by row in a loop.
**Introduction**
Bulk insertion of data into database table is a big overhead in application development. An approach would be to insert the records into the table using a loop in the application, this round trip approach consumes network and CPU resources and as such is not recommended. Microsoft ADO.Net provides the **SqlBulkCopy** class that lets you efficiently bulk load a SQL Server table with data from another source, but bulk loading an Oracle table can be done through the use of [Oracle Data Provider for .Net (ODP.Net)](http://www.oracle.com/technetwork/topics/dotnet/downloads/index.html).
**Bulk Insertion with ODP.Net**
ODP.Net has an array binding feature in which the records to be inserted are put in arrays and the arrays are passed to the ODP.Net OracleCommand class for insertion into the database table.This blog post would use a simple application that insert multiple customer records into a Customer table in an Oracle database. The source code is below.
// A customer DTO
public class CustomerDTO
{
public string Surname{get;set;}
public string FirstName{get;set;}
public string EmailAddress{get;set;}
}
The OracleDbConnector class that serves as wrapper around ODP.net to perform bulk insertion of data.
public class OracleDbConnector
{
private OracleConnection oracleConnection;
private OracleConnectionStringBuilder stringBuilder;
public OracleDbConnector(string dbUsername, string dbPassword, string dbServer)
{
stringBuilder = new OracleConnectionStringBuilder();
stringBuilder.DataSource = dbServer;
stringBuilder.UserID = dbUsername;
stringBuilder.Password = dbPassword;
oracleConnection = new OracleConnection();
oracleConnection.ConnectionString = stringBuilder.ConnectionString;
}
public bool UploadBulkData(List bulkData)
{
bool returnValue = false;
try
{
string query = @"insert into PCMS.Customer ( surname, firstName, emailAddress) values
(:surname, :firstName, :emailAddress)";
oracleConnection.Open();
using (var command = oracleConnection.CreateCommand())
{
command.CommandText = query;
command.CommandType = CommandType.Text;
command.BindByName = true;
// In order to use ArrayBinding, the ArrayBindCount property
// of OracleCommand object must be set to the number of records to be inserted
command.ArrayBindCount = bulkData.Count;
command.Parameters.Add(":surname", OracleDbType.Varchar2, bulkData.Select(c => c.Surname).ToArray(), ParameterDirection.Input);
command.Parameters.Add(":firstName", OracleDbType.Varchar2, bulkData.Select(c => c.FirstName).ToArray(), ParameterDirection.Input);
command.Parameters.Add(":emailAddress", OracleDbType.Varchar2, bulkData.Select(c => c.EmailAddress).ToArray(), ParameterDirection.Input);
int result = command.ExecuteNonQuery();
if (result == bulkData.Count)
returnValue = true;
}
}
catch (OracleException ex)
{
//Log error thrown
}
finally
{
oracleConnection.Close();
}
return returnValue;
}
}
An NUnit test case for the OracleDbConnector class.
using System;
using System.Collections.Generic;
using System.Linq;
using System.Text;
using System.Threading.Tasks;
using NUnit.Framework;
\[TestFixture\]
public class OracleDbConnectorTest
{
private OracleConnector oracleConnector;
\[TestFixtureSetUp\]
public void SetUpTest()
{
oracleConnector = new OracleConnector("UserId", "Password", "serverAddress");
}
\[Test\]
public void TestUploadBulkData()
{
List bulkData= new List();
bulkData.Add(new CustomerDTO("Ayobami","Adewole","xyz@abc.com"));
bulkData.Add(new CustomerDTO("John","Peter","john@abc.com"));
bulkData.Add(new CustomerDTO("Tunji","James","james@abc.com"));
Assert.IsTrue(oracleConnector.UploadBulkData(bulkData));
}
\[TestFixtureTearDown\]
public void TearDownTest()
{
oracleConnector = null;
}
}
}
### Frequently asked questions
**Why shouldn't I insert records into a database table in a loop?**
Inserting record by record makes a round trip for each one, which consumes network and CPU resources and is not recommended for bulk data.
**How do I bulk load an Oracle table from .NET?**
Use Oracle Data Provider for .NET (ODP.NET). Its array binding feature lets you put the records to insert into arrays and pass the arrays to the OracleCommand class. For SQL Server, ADO.NET provides the SqlBulkCopy class for the same job.
---
## Business Rules Management in Java with Drools
URL: https://www.ayobamiadewole.com/Blog/Business-Rules-Management-in-Java-with-Drools/
Category: Java
Published: 2015-01-10
Summary: Drools is a Java business rules management system: write rules in a .drl file, compile them through the KIE API into a stateless or stateful session, insert your data and fire the rules. The example enforces a minimum applicant age and is tested with JUnit.
**Introduction**
Business rules are constraints or conditions that define aspects of a business, they define how an organization or business operates; they include requirements, policies and conditional statements. Using Rules in an application provides an abstraction over changeable business logic; changing rules is faster than making changes to source codes in order to change application behaviours.
A business rule might state that the minimum age of an individual that would fill an online form should be 18, while another might be that the minimum balance in a bank account before withdrawal can occur is 100 Naira. Business rules are usually mined from use cases, systems specifications or user requirements
A business rules management system (BRMS) is a software that is used to define, execute and maintain business rules of an organization. At the heart of a BRMS is a business rules engine which executes business rules in a production environment. There are several BRMS in java which are matured and have been around for years, but Drools is widely used and most popular.
**Drools BRMS**
Drools is a BRMS tool written in Java and can be used in an Enterprise Java Application to manage business rules. It allows users to write and validate business rules. Drools provides a core Business Rules Engine (BRE), a web authoring and rules management application (Drools Workbench) and an Eclipse IDE plugin for core development.
Starting from version 6.0 drools implementation is based on PHREAK Algorithm which is a pattern matching algorithm for implementing production rules as opposed to an enhanced RETE algorithm that was used in the earlier versions. At the time of writing of this post, drools is currently in version 6.2 and can be downloaded [here](http://www.drools.org/), the codes used in this post is compatible with version 6.1 and later.
Rules in Drools can be organized or saved in files, in this case a .drl file or in database as well as having decision tables configured in excel files. Starting from version 6.0 drools introduced the KIE api which groups all the related projects together.
Drools introduces the concept of Stateless knowledge session which can be called like a function by passing data to it and getting response and it can be used for validation, calculation and route filtering. And Stateful knowledge session which allows iterative changes over time and can be used for monitoring, diagnostics, logistics and compliances.
**Getting Started**
I believe in explaining concepts using codes, lets start with an example that implements a business rule which states that the minimum age of an applicant should be 40. The following libraries are to be added to the project classpath to be able to use drools.
* kie-api-6.1.0.Final.jar
* drools-compiler-6.1.0.Final.jar
* drools-core-6.1.0.Final.jar
* drools-decisiontables-6.1.0.Final.jar
* kie-internal-6.1.0.Final.jar
* slf4j-api-1.7.7.jar
* slf4j-log4j12-1.7.7.jar
* log4j-1.2.17.jar
* xstream-1.4.7.jar
* mvel2-2.2.1.Final.jar
* protobuf-java-2.5.0.jar
* antlr-runtime-3.5.jar
An Applicant POJO should be defined to hold the data to be processed.
package com.poc.drools;
public class Applicant {
private String name;
private int age;
private boolean valid;
public String getName() {
return name;
}
public void setName(String name) {
this.name = name;
}
public int getAge() {
return age;
}
public void setAge(int age) {
this.age = age;
}
public boolean isValid() {
return valid;
}
public void setValid(boolean valid) {
this.valid = valid;
}
}
We can now define the rule to be processed by the rule eninge in a drools file and save it as ageRule.drl, this is a text file with .drl extension.
package com.poc.drools
import com.poc.drools.Applicant;
rule "Is applicant age valid"
dialect 'mvel'
when
$applicant : Applicant( age < 40 )
then
$applicant.setValid(false);
end
**Package** and **import** kyewords work just like in a regular java class file, a rule name must follow the **rule** keyword while mvel is the rule language dialect to use. The $applicant is the binding variable that gives access to object containing the data that would be inserted into the rule engine. Drools rules normally consist of the condition part which would be implemented inside **when** block and the action to be performed if the condition is met which would be put inside **then** block.
Once the rule has been defined in the drool file, a stateless or stateful session needs to be created using the Kie api and the drools file(s) passed to it for compilation along with the data to be processed before the rules would be fired. A stateful session is used in the codes below.
package com.poc.drools;
import java.io.File;
import org.drools.core.common.DefaultFactHandle;
import org.kie.api.KieBase;
import org.kie.api.KieBaseConfiguration;
import org.kie.api.KieServices;
import org.kie.api.builder.KieBuilder;
import org.kie.api.builder.KieFileSystem;
import org.kie.api.builder.ReleaseId;
import org.kie.api.runtime.KieContainer;
import org.kie.api.runtime.KieSession;
import org.kie.api.runtime.KieSessionConfiguration;
import org.kie.api.runtime.rule.FactHandle;
import org.kie.internal.io.ResourceFactory;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
public class RuleProcessor {
Logger logger=LoggerFactory.getLogger(RuleProcessor.class);
public Boolean isApplicantEligible(Applicant applicant) {
// String array was used because the rules can be splited into two or more files
String \[\] paths= new String\[1\];
paths\[0\]="C:\\\\Users\\\\AYOBAMI\\\\Documents\\\\workplace\\\\DroolsPOC\\\\src\\\\rules\\\\ageRule.drl";
KieServices kieServices = KieServices.Factory.get();
// Adds the drools file to the KieFileSystem for necessary compilation to occur
KieFileSystem kieFileSystem = kieServices.newKieFileSystem();
for (String path : paths) {
File file= new File(path);
kieFileSystem.write(ResourceFactory.newFileResource(file));
}
// Create the builder for the resources of the File System
KieBuilder kieBuilder = kieServices.newKieBuilder(kieFileSystem);
kieBuilder.buildAll();
// Get the Release ID
ReleaseId relaseId = kieBuilder.getKieModule().getReleaseId();
// Create the Container, wrapping the KieModule with the given ReleaseId
KieContainer kiecontainer =kieServices.newKieContainer(relaseId);
// Configure and create a KieContainer that reads the drools files
KieBaseConfiguration kieBaseConfiguration = kieServices.newKieBaseConfiguration();
KieBase kieBase = kiecontainer.newKieBase(kieBaseConfiguration);
// Configure and create the KieSession
KieSessionConfiguration kieSessionConfiguration = kieServices.newKieSessionConfiguration();
KieSession kieSession= kieBase.newKieSession(kieSessionConfiguration, null);
//FactHandle holds reference to the inserted object
FactHandle applicantFactHandle= kieSession.insert(applicant);
//execute rule
kieSession.fireAllRules();
//get the processed data out of the rule engine
applicant= (Applicant) ((DefaultFactHandle)applicantFactHandle).getObject();
//release and free memory
kieSession.dispose();
return applicant.isValid();
}
}
Below is the Junit testcase to test the RuleProcessor class.
package com.poc.drools.test;
import static org.junit.Assert.\*;
import org.junit.After;
import org.junit.Before;
import org.junit.Test;
import com.poc.drools.Applicant;
import com.poc.drools.RuleProcessor;
public class RuleProcessorTest {
private RuleProcessor ruleProcessor;
@Before
public void setUp() throws Exception {
ruleProcessor= new RuleProcessor();
}
@After
public void tearDown() throws Exception {
ruleProcessor=null;
}
@Test
public void testIsApplicantEligible() {
Applicant applicant = new Applicant();
applicant.setAge(16);
applicant.setName("Ayobami Adewole");
assertTrue(ruleProcessor.isApplicantEligible(applicant));
}
}
Once the rules have been fired, the rule engine will execute the rules and process the data, then appropriate action can then be taken on the processed data depending on the application logic.
The full source codes can be downloaded [here](/Blog/Files/DroolsPOC.rar). Subsequent blog posts would feature complex rules scenarios and their implementations in drools.
### Frequently asked questions
**What is a business rules management system?**
Software used to define, execute and maintain an organization's business rules. Its core is a rules engine that executes the rules in production. Using rules abstracts changeable business logic, so changing a rule is faster than changing source code.
**What is the difference between a stateless and a stateful Drools session?**
A stateless session is called like a function: pass data in and get a response, which suits validation, calculation and route filtering. A stateful session allows iterative changes over time, which suits monitoring, diagnostics, logistics and compliance.
**Where can Drools rules be stored?**
In .drl files, in a database, or in decision tables configured in Excel files. Drools 6.0 also introduced the KIE API, which groups the related projects together.
---
## Deserializing Json to a Java Object using Google’s Gson library
URL: https://www.ayobamiadewole.com/Blog/Deserializing-Json-to-a-Java-Object-using-Google-Gson-library/
Category: Java
Published: 2014-08-16
Summary: To deserialize JSON into a Java object with Google Gson, create a class whose field names match the JSON keys, then call gson.fromJson(json, YourClass.class) on a Gson instance built with GsonBuilder.
Javascript object notations (Json) is fast becoming the de facto standard or format for transferring, sharing and passing around data. Be it on the web, REST Service, a remote procedure call or even an ajax request. Json is light weight with little memory footprint when compared to an xml.
The content of a Json string in its raw form when observed looks gibberish. To make the content usable it needs to be deserialized or converted to a useable form usually a java object (POJO) or an array or list of objects depending on the jscon content.
A typical json string is as shown below
{"city":"Jos","country":"Nigeria","houseNumber":"13","lga":"Jos South",
"state":"Plateau","streetName":"Jonah Jann","village":"Bukuru","ward":"1"}
There are a lot of frameworks for deserializing json to a java object such as [json-rpc](http://software.dzhuvinov.com/json-rpc-2.0.html), [Gson](https://code.google.com/p/google-gson/), [Flexjson](http://flexjson.sourceforge.net/) and a whole lots of other open source libraries. Of all the libraries mentioned I would in this blog post demonstrate how to use google-Gson library to deserialize a json string to a java object. You can download the [Gson](https://code.google.com/p/google-gson/) library from [https://code.google.com/p/google-gson/](https://code.google.com/p/google-gson/).
To have the json string deserialized, a java object must be created that has the same fields names with the fields in the json string. There is a website that provides a service for viewing the content of a json string in a tree like manner. [http://jsonviewer.stack.hu](http://jsonviewer.stack.hu/)
Paste the json string in the text tab
And view the fields and the content from the Viewer tab
I would deserialize a json string that contains address details to an Address POJO, the address object follows the structure as seen from the json tree view above.
public class Address{
private String city;
private String country;
private String houseNumber;
private String lga;
private String state;
private String streetName;
private String village;
private String ward;
public String getCity() {
return city;
}
public void setCity(String city) {
this.city = city;
}
public String getCountry() {
return country;
}
public void setCountry(String country) {
this.country = country;
}
public String getHouseNumber() {
return houseNumber;
}
public void setHouseNumber(String houseNumber) {
this.houseNumber = houseNumber;
}
public String getLga() {
return lga;
}
public void setLga(String lga) {
this.lga = lga;
}
public String getState() {
return state;
}
public void setState(String state) {
this.state = state;
}
public String getStreetName() {
return streetName;
}
public void setStreetName(String streetName) {
this.streetName = streetName;
}
public String getVillage() {
return village;
}
public void setVillage(String village) {
this.village = village;
}
public String getWard() {
return ward;
}
public void setWard(String ward) {
this.ward = ward;
}
@Override
public String toString() {
return "Address \[city=" + city + ", country=" + country
+ ", houseNumber=" + houseNumber + ", lga=" + lga + ", state="
+ state + ", streetName=" + streetName + ", village=" + village
+ ", ward=" + ward + "\]";
}
}
To perform the deserialization with Gson is easy, create POJO classes to hold your data, import the packages com.google.gson.Gson and com.google.gson.GsonBuilder, to your project. Then create and instance of the Gson class and then perform the deserialization as shown below.
Gson gson = new GsonBuilder().create();
Address address=gson.fromJson(json, Address.class);
Voila, you have your json deserialized!
The source code listing is below.
package jsondeserializer
import com.google.gson.Gson;
import com.google.gson.GsonBuilder;
public class Tester {
public static void main(String\[\] args) {
String json ="{\\"city\\":\\"Jos\\",\\"country\\":\\"Nigeria\\",\\"houseNumber\\":\\"13\\",\\"lga\\":\\"Jos South\\",\\n" +
"\\"state\\":\\"Plateau\\",\\"streetName\\":\\"Jonah Jann\\",\\"village\\":\\"Bukuru\\",\\"ward\\":\\"1\\"}";
Gson gson = new GsonBuilder().create();
Address address=gson.fromJson(json, Address.class);
System.out.println(address.toString());
}
}
### Frequently asked questions
**How do I convert a JSON string to a Java object with Gson?**
Create a POJO with the same field names as the JSON string, import com.google.gson.Gson and com.google.gson.GsonBuilder, create an instance with new GsonBuilder().create(), then call gson.fromJson(json, Address.class) with your own class.
**How can I inspect the structure of a JSON string?**
The post uses the online viewer at jsonviewer.stack.hu: paste the JSON into the text tab and view its fields as a tree in the Viewer tab.
---
## How to enable .Net Framework 3.5 on Microsoft Windows Server 2012 R2
URL: https://www.ayobamiadewole.com/Blog/How-to-enable-Net-Framework-3-5-on-Microsoft-Windows-Server-2012-R2/
Category: Others
Published: 2014-07-20
Summary: Enabling .NET Framework 3.5 on Windows Server 2012 R2 without internet fails with "The source file could not be found". Copy the sxs folder from Windows Server 2012 setup media and run dism.exe with /Source and /LimitAccess.
Recently, I had to put on my System Administrator cap for couple of hours. I was to set up two Dell PowerEdge 1720 server computers for use as Test Servers. The two servers were to run Microsoft Windows Server 2012 R2 and that .Net framework 3.5 must be enabled on the servers as it is one of the requirements needed by the enterprise application to be installed on the servers.
Enabling .Net framework 3.5 on Windows Server 2012 R2 can be done through the Server Manager by clicking on Add Roles and Features and then under Features selecting .Net framework 3.5 or through Command Prompt or Windows Power Shell. As it is Microsoft’s custom to put the required files for required role or features in the side-by-side folder. One would have thought that .Net Framework 3.5 files should be in the folder also as it is in Windows Server 2012’s side-by-side folder.
So an attempt to enable .Net framework 3.5 on Windows Server 2012 R2 would give an error “that Installation of one or more roles, role services or features failed. The source file could not be found” like the one shown in the picture below. This means that the .Net framework 3.5 (which includes 3.0 and 2.0) files are not included in Windows Server 2012 R2 setup.

If the server is connected to the internet and it has Windows update enabled, the framework can be pulled from the internet and added to the Windows installation folder by the OS when enabling the feature. But the servers I was configuring had no internet connections which means that there was no way the framework could be pulled from the internet.
What I did was to copy the side-by-side folder from Windows Server 2012 setup, (not Windows Server 2012 R2 setup) since it contains the files needed to install the .Net 3.5 framework, I then ran Command Prompt as an administrator with the following commands.
dism.exe /online /enable-feature /featurename:NetFX3Serverfeatures /Source:D:\\sxs
To enable the feature
dism.exe /online /enable-feature /featurename:NetFX3 /Source:D:\\sxs /LimitAccess
To install the feature

where **D:\\sxs** is the path of the folder containing the required files that I copied from Windows Server 2012 setup side-by-side folder.
I hope I have been able to save someone precious time.
### Frequently asked questions
**Why does enabling .NET Framework 3.5 fail on Windows Server 2012 R2?**
You get "Installation of one or more roles, role services or features failed. The source file could not be found" because the .NET 3.5 files (which include 3.0 and 2.0) are not in the Windows Server 2012 R2 setup's side-by-side folder. With internet access and Windows Update enabled, the OS can pull them automatically.
**How do I install it on a server with no internet connection?**
Copy the side-by-side (sxs) folder from the Windows Server 2012 setup, not the R2 setup. Then, in an administrator Command Prompt, run dism.exe /online /enable-feature /featurename:NetFX3 /Source:D:\sxs /LimitAccess, where D:\sxs is the folder you copied.
---
## Lambda Expression in Java SE 8
URL: https://www.ayobamiadewole.com/Blog/Lambda-Expression-in-Java-SE-8/
Category: Java
Published: 2014-06-20
Summary: Java 8 lambda expressions let you pass code as a method argument without an anonymous class. The post shows them shortening event listener, thread and collection code such as filtering, sorting and querying.
**Introduction**
In Object Oriented programming languages, object is the first class citizen but reverse is the case in functional programming languages because functions are first class citizens in which they can be passed around as if they are variables this is seen in Haskell, javascript and other functional languges. Functional languages have other constructs that are not readily available in object oriented languages such as closure, lambda expressions and so on.
Lambda expression was not part of earlier versions of Java and as such, passing method or function as arguments was normally achieved through the use of anonymous class which was not elegant. But with the introduction of Lambda Expression in Java 8 the language can be made to behave like a functional language, though not with closure anywa. Thus, the introduction of Lambda Expression in Java 8 in a way bridges the gap the language has with functional programming language.
Lambda Expression is usually referred to as anonymous function, a function without a name. It is a shorthand that lets you declare a method where it is going to be used without specifying the method name, return type, access specifier. It enables you to treat code as data and use function as method arguments.
**Why you should care about Lambda Expression**
1. The introduction of lambda expression in java will make available the benefits of functional language in java.
2. Lambda expression provides a means to write clear and concise codes with the use of expressions.
3. Collection filtering, Iteration and Extraction can be greatly improved using Lambda expression.
**NB:** JDK 8 or a higher version is required
**Syntax**
(argument) -> (body)
Where there can be zero or more arguments, The arrow token is the java lambda operator and (body) contains one or more line of codes to be executed when the function is called.
**Examples**
(int a, int b) - > a\*b
(Person p) - > { return p.getAge();}
In the first example, the expression's arguments are the integer values a and b which would be used by the expression to return the output of the multiplication operation.
The second example takes an object person as argument while the expression returns the value from the getAge() method called on the object.
Prior to Java 8, codes to handle EventListener in swing were normally written using the anonymous class
btnOk.setOnAction( newEventHandler() {
@Override
public voidhandle(ActionEvent e) {
// codes to handle button event would be written here
}
});
With lambda expression, the EventListener code can be made to be elegant with less lines of codes as shown below
btnOk.setOnAction( e -> {
// codes to handle button event would be written here
});
Another example can be seen in Thread code where anonymous class codes can now be substituted for that of a lambda expression
new Thread(
() -> System.out.println("This is a seperate thread")
).start();
Furthermore, Lambda Expression can be used in collections where it can be used to simplify some operations such as filtering, sorting and even querying of items in a collection.
ArrayList arrayList= new ArrayList<>();
for(int i=1; i<=100; i++)
arrayList.add(i);
//without lambda expression
for(Integer i: arrayList){
System.out.println( i);
}
//with lambda expression
arrayList.forEach( i -> {System.out.println(i);});
From the codes above, it is glaring that lambda expression minimizes the lines of codes to be written, thus making it elegant.
In this blog post, I have been able to show how Lambda Expression can be made to bridge the gap between java and functional languages, while reducing the lines of code written in the process.
### Frequently asked questions
**What is a lambda expression in Java?**
An anonymous function: a shorthand that declares a method where it will be used, without a name, return type or access specifier. It lets you treat code as data and pass functions as method arguments. JDK 8 or higher is required.
**Why use lambda expressions?**
They give clear, concise code, improve collection filtering, iteration and extraction, and replace verbose anonymous classes (as in Swing event listeners and threads) with far fewer lines.
---
## How To Add Search Capability To .Net Applications Using Lucene.net
URL: https://www.ayobamiadewole.com/Blog/Add-Search-Functions-to -Net-Applications-Using-Lucene-net/
Category: Asp.Net
Published: 2014-01-31
Summary: Lucene.Net, a .NET port of the Lucene full-text search engine, can add search to an ASP.NET MVC app: create an index directory and IndexWriter, add Documents built from Fields, commit, then query the index with an IndexSearcher.
One of the key factors in determining if a software application is usable is if the users can navigate around it easily, while at the same time finding relevant information and resources through the provision of a search functionality. While it is easy to integrate Google or Bing search libraries into software applications, at times it is necessary to use a library that provides an in-depth search capabilities while at the same time furnishing the developers with search analytics. There are a lot of proprietary search libraries or frameworks that fall into these categories such as Excite. But there is an open source and robust search library that I have found very fascinating when I need to add search capabilities to .net applications; **Lucene.net**.
Lucene.net is a .net port of Lucene, an open source full text search engine written in java. Lucene.net when incorporated into .Net applications provides full text search functionality. And also, Lucene.Net can be used to index entity framework objects to facilitate easy searching, thanks to LINQ to Lucene project. The source code ofLucene.Net can be gotten from [https://github.com/apache/lucene.net](https://github.com/apache/lucene.net) and compiled or the compiled binaries from nugget **Install-Package Lucene.Net**
In this blog post, I will quickly demonstrate how Lucene.Net can be used in a .Net application to provide a full text search. Before we start writing codes, some Lucene concepts and terms need to be explained and clarified.
**Field**: this is a name, value pair dictionary or hashtable, the name can be title or subject of a blog post, while the value would be the text. The values of a field can be stored, indexed and analyzed.
**Document**: is a sequence of fields
**Directory**: this is where Lucene stores indexes and it can be in a folder on the system or in memory.
**IndexWriter**: this is the Lucene’s component that creates and optimizes indexes and also adds documents to indexes.
**Analyzer**: is the Lucene’s Component that extracts index keys or terms from the text.
**IndexReader**: this is the Lucene’s component that allows easy search and retrieval of indexed fields.
I will demonstrate the power of Lucene.net by using it to index the pages of an ASP.net MVC application. First, the binaries of Lucene.net needs to be added to the MVC application through nugget. Then a folder needs to be created inside App\_Data folder, I named the folder LuceneIndexes, when that is done, the next thing is to initialize the directory and indexwriter that Lucene.net will use and this is best done during application startup, by adding a LuceneSearchConfig class to App\_Start folder, with codes as shown below.
\[assembly: WebActivator.PostApplicationStartMethod(typeof(Blog.Web.App\_Start.LuceneSearchConfig),
"InitializeSearch")\]
\[assembly: WebActivator.ApplicationShutdownMethodAttribute(typeof(Blog.Web.App\_Start.
LuceneSearchConfig),"FinalizeSearch")\]
namespace Blog.Web.App\_Start
{
using Blog.Domain.Service;
using Lucene.Net.Analysis;
using Lucene.Net.Analysis.Standard;
using Lucene.Net.Documents;
using Lucene.Net.Index;
using Lucene.Net.QueryParsers;
using Lucene.Net.Search;
using Lucene.Net.Store;
using System;
using System.Collections.Generic;
using System.Linq;
using System.Threading.Tasks;
using System.Web;
public class LuceneSearchConfig
{
public static Directory directory;
public static Analyzer analyzer;
public static IndexWriter writer;
public static void InitializeSearch()
{
string directoryPath = AppDomain.CurrentDomain.BaseDirectory + @"\\App\_Data\\LuceneIndexes";
directory = FSDirectory.Open(directoryPath);
analyzer = new StandardAnalyzer(Lucene.Net.Util.Version.LUCENE\_30);
writer = new IndexWriter(directory, analyzer, IndexWriter.MaxFieldLength.UNLIMITED);
Task.Factory.StartNew(() => CreateIndex());
}
private static void CreateIndex()
{
IBlogService blogService = new BlogService(repository);
var pages = blogService.GetAllPages();
Document doc;
string pageUrl = string.Empty;
string pagePath = string.Empty;
foreach (var page in pages)
{
doc = new Document();
pageUrl = string.Concat("~/Blog/", page.PageViewName);
pagePath = string.Concat(AppDomain.CurrentDomain.BaseDirectory, @"\\Views\\MyBlog\\", page.PageViewName, ".cshtml");
doc.Add(new Field("postUrl", pageUrl, Field.Store.YES, Field.Index.NOT\_ANALYZED));
doc.Add(new Field("postTitle", page.PageTitle, Field.Store.YES, Field.Index.NOT\_ANALYZED));
doc.Add(new Field("postBody", pagePath, Field.Store.YES, Field.Index.ANALYZED));
writer.AddDocument(doc);
doc = null;
}
writer.Optimize();
writer.Commit();
writer.Dispose();
}
public static void FinalizeSearch()
{
directory.Dispose();
}
}
}
Let me break down the codes and explain it. The lines of codes below initializes the folder where the Lucene.net Indexes would be stored while at the same time instantiation of Analyzer and IndexWriter were done.
string directoryPath = AppDomain.CurrentDomain.BaseDirectory + @"\\App\_Data\\LuceneIndexes";
directory = FSDirectory.Open(directoryPath);
analyzer = new StandardAnalyzer(Lucene.Net.Util.Version.LUCENE\_30);
writer = new IndexWriter(directory, analyzer, IndexWriter.MaxFieldLength.UNLIMITED);
The fields to be indexed would be added to the Document object, before adding the object to the index writer as shown in the codes below.
doc = new Document();
pageUrl = string.Concat("~/Blog/", page.PageViewName);
pagePath = string.Concat(AppDomain.CurrentDomain.BaseDirectory,@"\\Views\\MyBlog\\", page.PageViewName, ".cshtml");
doc.Add(new Field("postUrl", pageUrl, Field.Store.YES, Field.Index.NOT\_ANALYZED));
doc.Add(new Field("postTitle", page.PageTitle, Field.Store.YES, Field.Index.NOT\_ANALYZED));
doc.Add(new Field("postBody", pagePath, Field.Store.YES, Field.Index.ANALYZED));
writer.AddDocument(doc);
After the indexes have been added to the document, the Optimize method of the IndexWriter is called to optimize the indexes for faster access, before calling the Commit and Dispose methods, which would save the indexes to the folder and close the IndexWriter.
writer.Optimize();
writer.Commit();
writer.Dispose();
Creating the query and making the search is relatively easy, once the indexes have been created. The LuceneIndexes directory needs to be opened once again, using the FSDirectory object which would then be passed into the constructor of IndexSearcher object. A Parser object would be created which would pass the search word or query before the Search method on the IndexSearcher is called. A POCO class was created to hold the results of the search which would in turn be passed to the view for further processing. The code is as shown below
public ActionResult Search(FormCollection formCollection)
{
List searchResults = new List ();
var query = formCollection\["search"\];
string indexDirectory = Server.MapPath("~/App\_Data/LuceneIndexes");
var analyzer = new StandardAnalyzer(Lucene.Net.Util.Version.LUCENE\_30);
IndexSearcher searcher = new IndexSearcher(FSDirectory.Open(indexDirectory));
var parser = new QueryParser(Lucene.Net.Util.Version.LUCENE\_30, "postBody", analyzer);
Query searchQuery = parser.Parse(query);
TopDocs hits = searcher.Search(searchQuery, 200);
int results = hits.TotalHits;
SearchResult searchResult = null;
for (int i = 0; i < results; i++)
{
Document doc = searcher.Doc(hits.ScoreDocs\[i\].Doc);
searchResult = new SearchResult();
searchResult.PostUrl = doc.Get("postUrl");
searchResult.PostTitle = doc.Get("postTitle");
searchResult.PostIntro = doc.Get("postIntro");
searchResults.Add(searchResult);
searchResult = null;
}
return View(searchResults);
}
public class SearchResult
{
public string PostUrl { get; set; }
public string PostTitle { get; set; }
public string PostIntro { get; set; }
}
In this blog post, I have demonstrated how Lucene.net can be quickly used in a .net an ASP.net MVC application to provide a full text search.
### Frequently asked questions
**What is Lucene.Net?**
A .NET port of Lucene, an open source full-text search engine written in Java. It gives .NET applications full text search, and can index Entity Framework objects through the LINQ to Lucene project.
**What are the core Lucene concepts?**
A Field is a name/value pair; a Document is a sequence of fields; a Directory is where indexes are stored (a folder or memory); the IndexWriter creates and optimizes indexes; the Analyzer extracts index terms from text; and the IndexReader retrieves indexed fields.
**How do I search an index once it is built?**
Open the index directory with an FSDirectory and pass it to an IndexSearcher, create a parser with the search word or query, then call Search on the IndexSearcher.
---
## Aspect Oriented Programming (AOP) In .Net Using C#
URL: https://www.ayobamiadewole.com/Blog/Aspect-Oriented-Programming-In-Net/
Category: C#
Published: 2013-09-08
Summary: Aspect-oriented programming keeps cross-cutting concerns such as logging, caching and auditing out of your business code. The post explains advice and pointcuts and demonstrates them with PostSharp, logging method entry and success.
I recently had a chit-chat with some developers and during our discussion, I asked them whether they do Aspect Oriented Programming (AOP), I was surprised with their responses, some of them have not heard of the concept before while others have heard of it but without bothering to investigate it. I further asked them how they manage cross cutting concerns in their codes and they told me their various implementations, in which I drew my conclusion; they have been writing repetitive codes that would definitely stink and be hard to manage.
Aspect oriented programming is a new concept in the software development world; it makes you write clean codes and prevents weaving of functional codes with non-functional codes, thereby reducing code repetition. By non-functional codes I mean cross cutting concerns like logging, caching, auditing and so on.
Imagine the kind of spaghetti codes that trying to log all methods in an enterprise application with a large codebase without the use of AOP to simplify it would produce. The ActionFilters in ASP.net MVC are examples of the implementation of AOP.
To fully grasp AOP, some terminology and concepts need to be understood. ADVICE- This is the code that performs cross cutting concern. A cross cutting concern can be logging or caching. It might be a piece of code that does logging in an application. POINTCUT -A Pointcut is that point in a program where the advice would be called and executed; it can be just before a method gets called or just before a class is instantiated.
There are cool AOP tools available for .net developers, that can make your AOP experience smooth and worthwhile, thus, preventing you from to re-inventing the wheel. The two most popular are PostSharp and CastleWindsor. I prefer the former because it is elegant and allows you to use the advice at the pointcut in a decorative pattern approach, this is not to say that the later is not robust I have equally used it in some projects. The example in this blog post uses PostSharp.
Navigate your browser to [www.postsharp.net](http://www.postsharp.net) to download the latest installation. The postsharp package when installed adds itself as a plugin to your installation of visual studio, so that subsequently you can just add the postsharp package to your project by right clicking the project in solution explorer to select Add Postsharp to project.
I will demonstrate this using a console application, create a console application in visual studio and then add postsharp library to the project. Add a new class to the project and name it MyLoggerClass. It is this class that will contain the cross cutting concern. In this case we will write on the console before the method is called and immediately after the method finishes execution. In real life scenario, you might want to log a method for auditing sake to know when and whether the method is called and if the method successfully executed.
Postsharp requires that any class to be used as an aspect class to be serializable, hence the decoration of the class with .Net's Serializable attribute. The MyLoggerClass will extend the Postsharp OnMethodBoundaryAspect, which makes it necessary for the MyLoggerClass to override the OnEntry and OnSuccess methods of OnMethodBoundaryAspect since I am concerned with logging when the method is called and after the method finishes exectution. The OnMethodBoundaryAspect has OnExit and OnException Methods that you can equally override if you are concerned with these events in your application.
The full code for the MyLoggerClass class is as shown below.
using PostSharp.Aspects;
using System;
using System.Collections.Generic;
using System.Linq;
using System.Text;
using System.Transactions;
namespace AOP
{
\[Serializable\]
public class MyLoggerClass : OnMethodBoundaryAspect
{
public override void OnEntry(MethodExecutionArgs args)
{
Console.WriteLine("This code got executed before the method was invoked");
}
public override void OnSuccess(MethodExecutionArgs args)
{
Console.WriteLine("This code got executed after the method was invoked");
}
}
}
In the Program.cs class of the console application, add a new class and name it InterceptedClass. Add a method to it and decorate the method with the attribute MyLoggerClass, as shown below.
public class InterceptedClass
{
\[MyLoggerClass\]
public void DoSomething()
{
Console.WriteLine("DoSomething method was called");
}
}
Then in the main method, instantiate the InterceptedClass and call the method you added to the class as shown below.
private static void Main(string\[\] args)
{
InterceptedClass interceptedClass = new InterceptedClass();
interceptedClass.DoSomething();
Console.ReadLine();
}
Run the program, you should see the screen as below.
This is a simple demonstration of AOP, this blog post should get any developer interested in AOP started, Postsharp has other cool features not described in this blog post. You can read further on the [Postsharp website](http://www.postsharp.net) .
Click [Here](/Blog/Files/AOP.zip) to download the complete source code of the console application.
### Frequently asked questions
**What is aspect-oriented programming?**
A way to write clean code that prevents weaving functional code with non-functional code, reducing repetition. The non-functional parts are cross-cutting concerns like logging, caching and auditing. ActionFilters in ASP.NET MVC are an example of AOP.
**What are advice and a pointcut?**
Advice is the code that performs a cross-cutting concern, such as logging. A pointcut is the point in a program where the advice is called and executed, for example just before a method runs.
**Which AOP tools are available for .NET?**
The post names PostSharp and Castle Windsor as the two most popular. The author prefers PostSharp because it lets you apply advice at the pointcut in a decorator-style approach.
---
## Uploading File with FineUploader Javascript Library in Asp.net MVC Application
URL: https://www.ayobamiadewole.com/Blog/Uploading-File-with-FineUploader-Javascript-Library-in-Asp-net-MVC-Application/
Category: Asp.Net
Published: 2013-05-30
Summary: FineUploader adds asynchronous file uploads with a progress bar to ASP.NET MVC, which has no file upload helper. Reference its JS and CSS, add a div for it to render into, and post to a controller action that receives the file as qqfile.
Often at times in a web application, there is always need for providing feature for uploading files to the server from the browser of a user of an application, though asp.net webform provides a fileupload server control that can be used for uploading file, in asp.net MVC there is no Html helper for file upload, this can be achieved by adding the html attribute type=”file” to the Html.TextBox helper to provide the file upload feature.
Building a responsive and asynchronous file upload is more than just adding html attribute type=”file” to the asp.net mvc Html.TextBox helper. One of such numerous libraries that does the job of providing asynchronous file uploading feature with progress bar to indicates the progress of the upload is fineuploader javascript library. It is customizable and easy to use, both the javascript file and css file can easily be modified to change the look and feel of the file upload control that would be displayed on the browser.
The library can be downloaded from [github](https://raw.github.com/Widen/fine-uploader/downloads/fineuploader-3.5.0.zip), after downloading the file extract the files and put the fineuploader-3.5.0.js file and its minified version in the scripts folder and the fineuploader-3.5.0.css file in the content folder in your asp.net mvc application.
In your view where you want to have the file upload feature add reference to the fineuploader-3.5.0.css and fineuploader-3.5.0.js files during development, during production you can use the minified version of the javascript file instead.
`
Now, ensure that the entire document has been loaded by the browser before executing any code, thus this can be achieved by adding the following inside the body tag in the page.
Before we dive into writing codes, there are some things that needs to be known, jQuery is much about finding an item in the DOM and then manipulating it. The base selector function in jQuery is **jQuery()** or **$()** used for locating or selecting elements in the page.
Elements in a page can be selected in three ways
Selecting elements by **Id** for example **$("#button1")** will return a reference to button1 in the page.
Selecting elements by **tag name** for example **$("h3")** will return a reference to all the h3 elements found in the DOM.
Lastly elements can be selected based on cascading style sheet class name, thus **$(".turnred")** will return a reference to all the elements having css class turnred.
Now, lets do some animations on an html text input with Id txtEfissy, this text input will possess a watermark effect in which when it has not yet recieved focus, it will contain the text "jQuery rocks" with silver colour, and border colour of black, but the moment it receives focus, the border colour turns green, the text "jQuery rocks" is removed and the text input now has a black colour, when it loses focus, if the text input still remain empty then the text "jQuery rocks" is put back into the text input.
$(document).ready(function () { $("h2").fadeIn("slow"); }); $(document).ready(function () { $("h2").fadeIn("slow"); });
Our Html text Input with water mark effect
the jquery code is below
$(document).ready(function () { $("#txtEfissy").css("color", "Silver"); $("#txtEfissy").css("border-color", "Black"); $("#txtEfissy").focus(function clearContent() { var s = $("#txtEfissy").val(); if (s.trim() == "jQuery rocks") { $("#txtEfissy").val("").css("color", "Black"); $("#txtEfissy").css("border-color", "Green"); } }).blur(function returnContent() { var s = $("#txtEfissy").val(); if (s.trim() == "") { $("#txtEfissy").val("jQuery rocks ").css("color", "Silver"); $("#txtEfissy").css("border-color", "Black"); } }); });
Now, this can equally be done on an ASP.net webform textbox server control, but to ensure that the textbox Id remains the same as the Id set at design time, the textbox's **ClientIDMode** is said to **static**.
I hope this article is helpful, I will suggest further reading at [jquery.com](http://jquery.com)
---
## A Client Server File Sharing Application
URL: https://www.ayobamiadewole.com/Blog/A-Client-Server-File-Sharing-Application/
Category: C#
Published: 2012-01-16
Summary: A C# client/server file transfer application built on TCP sockets, as two Windows Forms projects (FileSharingServer and FileSharingClient). TCP is chosen over UDP because lost packets are retransmitted, keeping files intact.
This blog post is a client/server file sharing or transfer application in C#, the application is made up of two projects, it can be tested on a single computer but, its capability will be best seen if tested on two computers, one running as a client while the other is a server.
Before we dive into coding, its essential to understand **Socket** which is the most important aspect of network programming.
Socket is an object that represents a low level access point to the Internet Protocol(IP) stack, it is used to send and receive data, thus it can be opened and closed, the data to be sent is always sent in block known as **Packet**.
Packets must contain the IP address of both the source of the packets and the destination computer where the data is being sent, and optionally it may contain a **Port** number. A port number is between 1 and 65,535. A port is a communication channel or endpoints on which computers can communicate. It is always recommended that programs use port number higher than 1024 to avoid conflicts with other applications running on the system, because no two applications can use the same port.
Packets containing port numbers can be sent using **UDP**(User Datagram Protocol) or **TCP/IP**(Transmission control protocol). UDP is easier to use than TCP because TCP is more complex and has longer latencies, but when the integrity of the data to be transferred is more important than performance, then TCP is prefered to UDP, and thus for our file sharing application TCP/IP will be used because it guarantees that our file does not become corrupt while being transfered and if during the transmission process a packet is loss, it is retransmitted thus making sure that our file integrity is maintained.
Thus, this application will allow you to send any file from one computer to another, personally I have used it to send a 350mb file from one desktop PC to another.
Now to get started, create two new windows forms applications one named FileSharingServer and the other FileSharingClient.
Now, for the FileSharingClient windows form application add three textboxes and two buttons to the form just like the screen below.
Rename the textboxes and buttons appropriately.
This is the code for the file sharing client application
using System;
using System.Collections.Generic;
using System.ComponentModel;
using System.Data;
using System.Drawing;
using System.Linq;
using System.Text;
using System.Windows.Forms;
using System.Threading.Tasks;
using System.Net;
using System.Net.Sockets;
using System.Net.NetworkInformation;
using System.IO;
namespace FileSharingClient
{
public partial class Form1 : Form
{
private static string shortFileName = "";
private static string fileName = "";
public Form1()
{
InitializeComponent();
}
private void btnBrowse\_Click(object sender, EventArgs e)
{
OpenFileDialog dlg = new OpenFileDialog();
dlg.Title = "File Sharing Client";
dlg.ShowDialog();
txtFile.Text = dlg.FileName;
fileName = dlg.FileName;
shortFileName = dlg.SafeFileName;
}
private void btnSend\_Click(object sender, EventArgs e)
{
string ipAddress = txtIPAddress.Text;
int port = int.Parse(txtHost.Text);
string fileName = txtFile.Text;
Task.Factory.StartNew(() => SendFile(ipAddress,port,
fileName,shortFileName));
MessageBox.Show("File Sent");
}
public void SendFile(string remoteHostIP, int remoteHostPort
, string longFileName, string shortFileName)
{
try
{
if(!string.IsNullOrEmpty(remoteHostIP))
{
byte\[\] fileNameByte = Encoding.ASCII.GetBytes
(shortFileName);
byte\[\] fileData = File.ReadAllBytes(longFileName);
byte\[\] clientData = new byte\[4 + fileNameByte.Length
+ fileData.Length\];
byte\[\] fileNameLen = BitConverter.GetBytes(
fileNameByte.Length);
fileNameLen.CopyTo(clientData, 0);
fileNameByte.CopyTo(clientData, 4);
fileData.CopyTo(clientData, 4 + fileNameByte.Length);
TcpClient clientSocket = new TcpClient(remoteHostIP,
remoteHostPort);
NetworkStream networkStream = clientSocket.GetStream();
networkStream.Write(clientData, 0, clientData.GetLength
(0));
networkStream.Close();
}
}
catch
{
}
}
}
}
Note the following namespaces were added to the windows form application
System.Threading.Tasks;
the namespace above is used to include the .Net Parallel computing classes
System.Net;
System.Net.Sockets;
System.Net.NetworkInformation;
the three namespaces above contain the .Net classes used for Network programming
System.IO;
the namespace above contains classes used for file operations
When the browse button is clicked an object of OpenFileDialog is created to open a dialog to get the file name of the file to be sent. When the send button is clicked, the SendFile method is called and handled in parallel so that the main form user interface does not get frozen while the file is being sent and the processors are fully utilized in a multi-core environment.
The SendFile method accepts IP address and port number of the destination computer as well as the file path and file name. Both the file name and the file are converted to bytes and sent to the destination computer using the TCPCLient and NetworkStream classes object created.
The user interface of the file sharing client application is shown below when run.
The source code for the server is
using System;
using System.Collections.Generic;
using System.ComponentModel;
using System.Data;
using System.Drawing;
using System.Linq;
using System.Text;
using System.Windows.Forms;
using System.Net;
using System.Net.Sockets;
using System.Net.NetworkInformation;
using System.IO;
using System.Threading.Tasks;
namespace FileSharingServer
{
public partial class Form1 : Form
{
public delegate void FileRecievedEventHandler(object source,
string fileName);
public event FileRecievedEventHandler NewFileRecieved;
public Form1()
{
InitializeComponent();
}
private void Form1\_Load(object sender, EventArgs e)
{
this.NewFileRecieved+=new FileRecievedEventHandler
(Form1\_NewFileRecieved);
}
private void Form1\_NewFileRecieved(object sender, string
fileName)
{
this.BeginInvoke(
new Action(
delegate()
{
MessageBox.Show("New File Recieved\\n"+fileName);
System.Diagnostics.Process.Start("explorer", @"c:\\");
}));
}
private void btnListen\_Click(object sender, EventArgs e)
{
int port = int.Parse(txtHost.Text);
Task.Factory.StartNew(() => HandleIncomingFile(port));
MessageBox.Show("Listening on port"+port);
}
public void HandleIncomingFile(int port)
{
try
{
TcpListener tcpListener = new TcpListener(port);
tcpListener.Start();
while (true)
{
Socket handlerSocket = tcpListener.AcceptSocket();
if (handlerSocket.Connected)
{
string fileName = string.Empty;
NetworkStream networkStream = new NetworkStream
(handlerSocket);
int thisRead = 0;
int blockSize = 1024;
Byte\[\] dataByte = new Byte\[blockSize\];
lock (this)
{
string folderPath = @"c:\\";
handlerSocket.Receive(dataByte);
int fileNameLen = BitConverter.ToInt32(dataByte,
0);
fileName = Encoding.ASCII.GetString(dataByte, 4,
fileNameLen);
Stream fileStream = File.OpenWrite(folderPath +
fileName);
fileStream.Write(dataByte, 4+fileNameLen,(
1024-(4+fileNameLen)));
while (true)
{
thisRead = networkStream.Read(dataByte, 0,
blockSize);
fileStream.Write(dataByte, 0,thisRead);
if (thisRead == 0)
break;
}
fileStream.Close();
}
if (NewFileRecieved != null)
{
NewFileRecieved(this, fileName);
}
handlerSocket = null;
}
}
}
catch
{
}
}
}
}
At the file sharing server application, a port number is supplied, on which the server will be listening to an income file to be recieved.
Just like the file sharing client application, the start listening button when clicked, invokes the HandleIncomingFile method in parallel. A TcpListener object is created to start listening for incoming file at the specified port, when a connection is received the a file with the same name as the file sent from the client is reconstructed from the received bytes and saved to the C drive and then an event is fired to indicate on the server user interface that a new file has been received.
When the event is fired, all subscribers to the event are notified and in this case the event handler method **Form1\_NewFileRecieved** is invoked and the code to display a message box and open the folder containing the file received is wrapped around the form BeginInvoke method to avoid thread errors.
The Complete source code of the two applications is available for download [Here](/Blog/Files/FileSharingSharing.rar)
### Frequently asked questions
**Why use TCP rather than UDP for file transfer?**
UDP is easier to use and has lower latency, but TCP guarantees the file does not become corrupt in transit: if a packet is lost it is retransmitted. When data integrity matters more than performance, TCP is preferred.
**Which port number should a network application use?**
A port number is between 1 and 65,535. Using a number higher than 1024 is recommended to avoid conflicts with other applications, because no two applications can use the same port.
---
## How to create shaped or irregular window in WPF
URL: https://www.ayobamiadewole.com/Blog/How-to-create-shaped-or-irregular-window-in-WPF/
Category: WPF
Published: 2012-01-09
Summary: To make a rounded or irregular WPF window, design a PNG with rounded corners and set AllowsTransparency="True", WindowStyle="None" and a transparent background. You must then add your own minimize and close buttons and handle MouseLeftButtonDown to drag it.
With windows presentation foundation, building a shaped or irregular window is relatively easy and can be done with minimal effort.
In this post, I will take you through how you can build a window in WPF that has round edges, using Visual Studio 2010 and C#.
The first thing is to create a new WPF application by clicking on the **File** menu, click **New** and then select **New Project** , under the **Installed Templates** , click **Visual C#**, select **Windows** and then click on **WPF Application** and rename it to **ShapedWindow** or any name of your choice.
Then fire open your image processing Software, in my case I prefer to use Adobe Photoshop or Fireworks and design a new image with rounded corners, then save it as Portable Network Graphic format .png
The next thing to do is to set some WPF window properties of MainWindow.xaml
AllowsTransparency="True"
OpacityMask="White"
WindowStyle="None"
Background="Transparent"
And set the background property of the grid in the main window to the Image that was created earlier.
Then run the program and you have the your shaped window.
But as you can see having a shaped window does not come without some payment, the normal window control box that used to be at the top right hand corner of the window is not there again and the window cannot be dragged around when left mouse button is hold down like a normal window.
We can circumvent these problems by writing some lines of code. First add two buttons to the top right hand corner of the window to serve as the window’s minimize and close button.
But for us to be able to drag the window, the window’s MouseLeftButtonDown event must be handled.
The full source code is
using System;
using System.Collections.Generic;
using System.Linq;
using System.Text;
using System.Windows;
using System.Windows.Controls;
using System.Windows.Data;
using System.Windows.Documents;
using System.Windows.Input;
using System.Windows.Media;
using System.Windows.Media.Imaging;
using System.Windows.Navigation;
using System.Windows.Shapes;
namespace ShapedWindow
{
/// < summary>
/// Interaction logic for MainWindow.xaml
/// < / summary>
public partial class MainWindow : Window
{
public MainWindow()
{
InitializeComponent();
}
private void button1\_Click(object sender, RoutedEventArgs e)
{
this.WindowState = WindowState.Minimized;
}
private void button2\_Click(object sender, RoutedEventArgs e)
{
this.Close();
}
private void Window\_MouseLeftButtonDown(object sender,
MouseButtonEventArgs e)
{
this.DragMove();
}
}
}
Now we now have a window that is shaped and can be dragged, minimized and closed.
The Source Code is available for download [Here](/Blog/Files/ShapedWindow.rar)
### Frequently asked questions
**Which window properties create a shaped WPF window?**
On MainWindow.xaml set AllowsTransparency="True", OpacityMask="White", WindowStyle="None" and Background="Transparent", then set the main grid's background to a PNG image designed with rounded corners.
**Why can't I move, minimize or close the shaped window?**
Removing the standard window chrome also removes the control box and the ability to drag the window. Add your own minimize and close buttons in the top right corner and handle the window's MouseLeftButtonDown event to make it draggable.
---
## Update requires a valid UpdateCommand when passed DataRow collection with modified rows
URL: https://www.ayobamiadewole.com/Blog/Update-requires-a-valid-UpdateCommand-when-passed-DataRow-collection-with-modified-rows/
Category: C#
Published: 2011-12-21
Summary: The "Update requires a valid UpdateCommand" error appears when a typed dataset contains a table without a primary key. Delete the table from the dataset, give it a primary key, and drag it back in.
This is one of those frustrating errors that one encounters when using Typed dataset and trying to update a table in the dataset that doesnot contain a primary key.

To correct the error, just delete the table that generates the error from the dataset, from the server explorer, edit the table and give it a primary key, then re-drag it on the dataset and you are
good to go.

### Frequently asked questions
**What causes the "Update requires a valid UpdateCommand when passed DataRow collection with modified rows" error?**
It occurs when you use a typed dataset and try to update a table in the dataset that does not contain a primary key.
**How do I fix it?**
Delete the table that generates the error from the dataset, edit the table in Server Explorer to give it a primary key, then drag it onto the dataset again.
---
## How to Pass MCTS 070515 Certification Exam
URL: https://www.ayobamiadewole.com/Blog/How-to-Pass-MCTS-070515-Certification-Exam/
Category: Asp.Net
Published: 2011-12-20
Summary: Advice for passing Microsoft's MCTS 70-515 (Web Applications Development with .NET Framework 4) exam: start preparing at least two months ahead, use the Northrup and Snell training kit, and study the six exam objective areas and their weightings.
Being certified is good, it a marker that indicates that you have a mastery of a technology, but it can never be substituted for on field experience.
As a certified professional, coupled with your on field experience, you have an edge and advantage over others when it comes to looking for job.
The acceptability of Microsoft based technology certifications is growing, as an MCTS you have access to numerous resources and materials that can make you self-sufficient and empowered to upgrade on your own.
To prepare for Microsoft Certified Technology Specialist(MCTS) in Web Applications development with Microsoft .Net Framework 4 exam is not too hard, as somebody who is already familiar with developing web application using ASP.net 4.0, but for someone who is just starting web development with Asp.net, it might not be easy.
You must start preparing at least two months before the day you intend to sit for the exam, the book by Tony NorThrup and Mike Snell [MCTS Self-Paced Training Kit (Exam 70-515)](http://www.amazon.com/MCTS-Self-Paced-Training-Exam-70-515/product-reviews/0735627401?pageNumber=2) is good and it will put you through what it takes to pass the exam.
I will recommend that you read MSDN documentations on the topics below, I will also suggest that you visit [this page](http://www.certsandprogs.com/search/label/70-515#axzz1ejBK2kzC) as well
This is the exam objective and the percentage obtainable
1 Developing Web Forms Pages (19%)
• 1.1 Configure Web Forms pages.
• 1.2 Implement master pages & themes.
• 1.3 Implement globalization.
• 1.4 Handle page life cycle events.
• 1.5 Implement caching.
• 1.6 Manage state.
2 Developing and Using Web Forms Controls (18%)
• 2.1 Validate user input.
• 2.2 Create page layout.
• 2.3 Implement user controls.
• 2.4 Implement server controls.
• 2.5 Manipulate user interface controls from code-behind.
3 Implementing Client-Side Scripting and AJAX (16%)
• 3.1 Add dynamic features to a page by using JavaScript.
• 3.2 Alter a page dynamically by manipulating the DOM.
• 3.3 Handle JavaScript events.
• 3.4 Implement ASP.NET AJAX.
• 3.5 Implement AJAX by using jQuery.
4 Configuring and Extending a Web Application (15%)
• 4.1 Configure authentication & authorization.
• 4.2 Configure providers.
• 4.3 Create and configure HttpHandlers and HttpModules.
• 4.4 Configure initialization and error handling.
• 4.5 Reference and configure ASMX and WCF services.
• 4.6 Configure projects and solutions, and reference assemblies.
• 4.7 Debug a Web application.
• 4.8 Deploy a Web application.
5 Displaying and Manipulating Data (19%)
• 5.1 Implement data-bound controls.
• 5.2 Implement DataSource controls.
• 5.3 Query and manipulate data by using LINQ.
• 5.4 Create and consume a data service.
• 5.5 Create and configure a Dynamic Data project.
6 Developing a Web Application by Using ASP.NET MVC 2 (13%)
• 6.1 Create custom routes.
• 6.2 Create controllers & actions.
• 6.3 Structure an ASP.NET MVC application.
• 6.4 Create and customize views.
Wish you best of luck in the exam!
### Frequently asked questions
**How long should I prepare for the MCTS 70-515 exam?**
Start at least two months before the day you intend to sit for it. The post recommends the MCTS Self-Paced Training Kit (Exam 70-515) by Tony Northrup and Mike Snell, plus MSDN documentation on the exam topics.
**What does the 70-515 exam cover?**
Six objective areas: Web Forms pages (19%), Web Forms controls (18%), client-side scripting and AJAX (16%), configuring and extending a web application (15%), displaying and manipulating data (19%), and ASP.NET MVC 2 (13%).
---
## Introduction to Lua Programming Language
URL: https://www.ayobamiadewole.com/Blog/Introduction-to-Lua-Programming-Language/
Category: Lua
Published: 2011-12-06
Summary: An introduction to Lua, a small interpreted language created in 1993 to be embedded in or used alongside C. The author chose it for writing IVR scripts on an IP PABX, and the post ends with the traditional Hello World example.
At a point in time, I worked on an Interactive Voice Response(IVR) application using an IP PABX that uses Lua as one of it scripting languages. Since I had in one time or the other worked and used the other languages that can be used in writing scripts for the PABX, I decided to pick Lua programming language as my choice, for writing scripts to be executed by the IP PABX.
Prior to that time, I had only heard of Lua being used as the scripting engine for the popular game World of Warcraft, I knew I was about to learn a new language entirely, so the first thing I did was to open my Firefox and do some background check about Lua.
Then I started the learning process, and along the line, I fell in love with it because though it is interpreted, it is extremely the fastest among scripting languages. And I have decided I will continouslly blog about it.
Lua which means moon

in Portugese is a programming language developed by Roberto Ierusalimschy and Waldemar Luiz in 1993 and was written with C language and in fact the authors intention then was to use Lua to do what C could not do, a kind of C extension. It was originally designed to be integrated with software written in C and other conventional languages. It is a simple and small language yet powerful because it can run on virtually any device.
Lua can be embedded in an application, for example I might have a portion of an application that I want Lua to handle while C# handles the rest, it can stand alone and also it can be used together with C language.
Now lets start programming with Lua
Lua has a syntax close to C language, so it wont be add from somebody with a C background to quickly grasp. You can download Lua from [http://www.lua.org/download.html](http://www.lua.org/download.html)
As its the custom in the programming world to always display Hello World, so we have
print("Hello World")
which displays hello world on the console window.

My subsequent blog posts will always contain cheat sheets and Lua codes that I have worked on.
---
## Mixed Mode Assembly Error
URL: https://www.ayobamiadewole.com/Blog/Mixed-Mode-Assembly-Error/
Category: C#
Published: 2011-12-05
Summary: The mixed mode assembly error happens when a project references a library built for an older .NET runtime, such as an old MySql.Data build in a WPF 4.0 app. Adding an app.config with useLegacyV2RuntimeActivationPolicy="true" fixes it.
I first encountered this error when I was building a small media player using WPF 4.0 and the embeddable open source database MySql. I added a link to the MySql.Data.MySqlClient library which was built on a lower version of the .Net framework than the one which the current application is running on. The screen is as shown below
In order to correct the error, an app.config file must be added to the project and then the following code is copied into the configuration file.
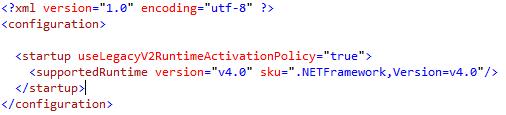 />
### Frequently asked questions
**What causes the "Mixed mode assembly is built against version v2.0.50727" error?**
It occurs when an application references a library that was built on a lower version of the .NET framework than the one the application is running on. The author hit it in a WPF 4.0 app that referenced the MySql.Data.MySqlClient library.
**How do I fix the mixed mode assembly error?**
Add an app.config file to the project containing a element with useLegacyV2RuntimeActivationPolicy="true" and a entry.
---
## How to build x264/libx264.dll in Windows
URL: https://www.ayobamiadewole.com/Blog/How-to-build-x264-or-libx264.dll-in-Windows/
Category: Others
Published: 2011-11-21
Summary: How to build the x264 video encoder on Windows with MinGW: run ./configure and make in the MinGW shell for x264.exe, configure with --disable-cli --enable-shared to get libx264.dll, then run LIB /DEF:libx264.def for a Visual Studio .lib.
For someone coming from a windows background, where you do virtually everything, using GUI probably with Visual studio or an equivalent IDE, compiling a program from the command line can be a daunting task.
This blog post will guide you through compiling and building the popular open source video encoding library on windows using the MinGW(Minimalist GNU on Windows).
First you need to download the x264 source code from [http://x264.nl/](http://x264.nl/) Or if you know how to use git, you can git clone the x264 from git://git.videolan.org/x264.git.
Then you should download MinGW from [http://sourceforge.net/projects/mingw/files](http://sourceforge.net/projects/mingw/files) Download the mingw-get-inst-20111118.exe (591.9 kB) install it and during the installation steps, select all the check boxes.
After the installation is completed, then from Start button , click All program, then click MinGW and then Click on MinGW shell, this brings up the following window
From the msys shell change your directory to the location where your x264 source code is, in my own case the x264 code is in the c: drive so I will simply Type **cd** **c:\\x264**
Then type **./configure** and press enter, this screen waits for some seconds and the bring
Then you can now type **make** and press enter, this will bring up the window below, showing the progress of the compilation process.
After the compilation is finished, if you look into your x264 directory you will find **x264.exe** file there.
Now compiling the x264 into a dynamic link library that can be used in Visual studio takes another process entirely. Open the MinGW bash once again and change the directory to the location of your x264 source code, just like you did previously.
Then type
**./configure --disable-cli --enable-shared --extra-ldflags=-Wl,--output-def=libx264-120.def**
or just**
./configure --disable-cli --enable-shared --extra-ldflags=-Wl,--output-def=libx264.def**
Now in libx264-120.def “120” is the version of the x264 you are using, you can find the version of the x264 you are using by opening the x264.h file in your x264 source folder you will see something like this **#define X264\_BUILD 120** depending on your version.
You can now type the **make** command and press enter and you will find the **libx264-120.dll** in your x264 source folder. Then rename **libx264-120.dll** to **libx264.dll** and you have you dynamic link library to work with.
If you wish to generate the Visual Studio .lib file to work with then open a Visual Studio command prompt, and change the directory to the location of the x264 source .
Then run this command
**LIB /DEF:libx264.def**
Then press enter
And your libx264.lib would be generated.
### Frequently asked questions
**How do I compile x264 on Windows?**
Download the x264 source (or git clone it), install MinGW with all the options selected, open the MinGW shell and change to the x264 folder. Run ./configure and then make; x264.exe appears in the source folder.
**How do I build libx264.dll?**
Run ./configure --disable-cli --enable-shared --extra-ldflags=-Wl,--output-def=libx264-120.def, then make. The 120 is your x264 build number, found as X264_BUILD in x264.h. Rename the resulting libx264-120.dll to libx264.dll.
**How do I generate the .lib file for Visual Studio?**
Open a Visual Studio command prompt, change to the x264 source folder and run LIB /DEF:libx264.def.
---
## Why good programming principles are not being taught in school
URL: https://www.ayobamiadewole.com/Blog/Why-good-programming-principles-are-not-being-taught-in-school/
Category: My Views
Published: 2011-11-21
Summary: Argues that schools teach programming basics but not principles like dependency injection, DRY and clean code, because these come from experience, reading books and reading other people's source code. Good programming is measured by years of experience, not academic level.
At times I do wonder why good programming principles like Dependecy injection, Dont repeat yourself(DRY) principle, clean code and other principles are not being taught in schools.
Having obtained a National Diploma(ND) in Computer Science and almost completing a degree (B.Tech) in Computer Science, I felt like a complete idiot to have gone to the university to study Computer Science, because there is great discrepancy from being an academic programmer and a developer. Quite alright, I was taught the rudiments of programming in school, (control structures, data structures and some programming constructs), it was not until I got into the business world that I knew I am in for a big challenge!
Computer science is a field in which new technologies are being developed every day, that you just have to keep updating yourself, or else you become obsolote.
I have come to realI have come to realise that good principles come with experience, Programing in school is to get you started, the rest you are on your own. Though while in school you are supposed to be taught good programing practices, some schools do it others donot.
Teachers who are professional programmers can teach good programming principles, but it is impossible for them to teach good programming while in classes, because they do not have the amount of time required to teach good programming concepts and principles.
Thus, developing and acquiring good programming principles is a personal effort that comes only with practices, reading books and reading other programmers source codes. Thus, being a good programmer is not measured on academic level, but on years of experiences.
Therefore, programming is considered as an art and not a science.
---
## My First Blog Post
URL: https://www.ayobamiadewole.com/Blog/My-First-Blog-Post/
Category: Others
Published: 2010-01-20
Summary: The author's first blog post: a C++ console program from a university class assignment, also ported to C#, that prints a pyramid of a chosen height built from a chosen character.
This is my first blog post as a blogger, originally located at felatuns.blogspot.com. It was an assignment that was given to my class when we were in the third year in the university. It is a C++ console program that is to display a pyramid on the console window.
The pyramid height is to be supplied as well as the character used in building the pyramid.
I have equally ported the C++ program to C#
C++
# include
# include
void main()
{
int height;
char design;
cout<"enter pyramid height";
cin>>height;
cout<<"enter pyramid design";
cin>>design>>endl;
for (int i = 0; i < height; i++)
{
for (int k = i; k < height; k++)
{
cout<<" ";
}
for (int j = 2 \* i + 1; j > 0; j--)
{
cout<< design
}
cout<<""<< endl
}
getch();
}
C#
using System;
using System.Collections.Generic;
using System.Linq;
using System.Text;
namespace Pyramid
{
class Program
{
static void Main(string\[\] args)
{
int height;
char design;
Console.Write("enter pyramid height ");
height = int.Parse(Console.ReadLine());
Console.WriteLine("");
Console.WriteLine("");
Console.Write("enter pyramid design ");
design = char.Parse(Console.ReadLine());
Console.WriteLine("");
Console.WriteLine("");
for (int i = 0; i < height; i++)
{
for (int k = i; k < height; k++)
{
Console.Write(" ");
}
for (int j = 2 \* i + 1; j > 0; j--)
{
Console.Write(design);
}
Console.WriteLine("");
}
Console.ReadLine();
}
}
}
This is the program output after having supplied 30 as the pyramid height and 8 as the
pyramid design.
